HW1
Class: CSCE-313
Notes:
1. Exploring OverlayFS
1.1 Background
When you run a Docker container, install a software update, or use a live USB Linux system, something clever is happening under the hood: the operating system is layering filesystems on top of each other. OverlayFS (Overlay Filesystem) is the Linux kernel feature that makes this possible.
The core idea is simple. You have a lower directory that is read-only—think of it as a snapshot or a base image. You have an upper directory that is read-write. OverlayFS overlays the upper on top of the lower and presents a single unified merged view to the user. When you read a file, the kernel checks the upper directory first; if it isn't there, it falls back to the lower. When you write a file, changes go only into the upper directory—the lower is never touched. A work directory is also required by the kernel as internal scratch space for atomic operations.
This design has a wonderful property: you can give many users or containers their own private upper directory layered over the same lower directory, and each sees what looks like a complete, independent filesystem—without duplicating all the data.
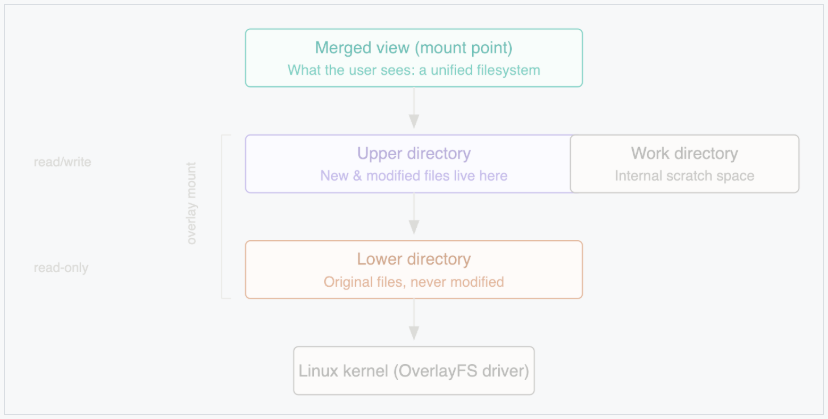
In this homework problem you will set up OverlayFS by hand on Ubuntu Linux, poke at it from multiple angles, and develop an intuition for how it works.
1.2 Prerequisites
You need an Ubuntu Linux machine (22.04 or 24.04 recommended). A virtual machine or a cloud instance (e.g., your GCP VM) is perfectly fine. You will need sudo (administrator) access. No special packages are required—OverlayFS is built into the Linux kernel.
Before you begin, verify that OverlayFS is available. You should see a line containing overlay. If not, try sudo modprobe overlay and run the check again.
grep overlay /proc/filesystems
1.3 Part I: Setting Up Your First Overlay Mount
1.3.1 Create the directory structure
Run the following commands. Each creates one of the four directories that OverlayFS needs.
mkdir -p ~/overlayfs-lab/{lower,upper,work,merged}
ls ~/overlayfs-lab/
Question 1: In your own words, the purpose of each of the four directories you just created? (4–5 sentences total is fine.)
Answer:
So basically each directory plays a specific role in how OverlayFS builds that “combined” filesystem view.
- The lower directory is like the base layer. It's read-only, so nothing ever gets modified here. We can think of it like a snapshot or a template that everything starts from.
- The upper directory is where all the changes go. Any new files, edits, or deletions are stored here, so this is the only layer that actually gets modified.
- The work directory is kind of behind-the-scenes. The kernel uses it as temporary scratch space to handle atomic operations safely, things like moving or copying files. We don't interact with it directly.
- The merged directory is what we actually see and use. It combines the lower and upper layers into one abstracted view, so it looks like a normal filesystem even though it's really built from more layers.
1.3.2 Populate the lower directory
The lower directory acts as your base, read-only layer. Put some files in it:
echo "I am from the lower layer" > ~/overlayfs-lab/lower/base_file.txt
echo "Another original file" > ~/overlayfs-lab/lower/original.txt
1.3.3 Mount the overlay
Now instruct the kernel to create the overlay:
sudo mount -t overlay overlay -o lowerdir=/home/macc/overlayfs-lab/lower,upperdir=/home/macc/overlayfs-lab/upper,workdir=/home/macc/overlayfs-lab/work /home/macc/overlayfs-lab/merged

mount | grep overlay # Confirm the mount succeeded
- Note I had to use absolute paths here
~was not expanded insidelowerdir,upperdir, andworkdir
Question 2: Copy the output of mount | grep overlay into your report. Identify which part of the output corresponds to each of the four directories.
Answer
$ mount | grep overlay
overlay on /home/macc/overlayfs-lab/merged type overlay (rw,relatime,lowerdir=/home/macc/overlayfs-lab/lower,upperdir=/home/macc/overlayfs-lab/upper,workdir=/home/macc/overlayfs-lab/work,uuid=on,nouserxattr)
The mount | grep overlay output shows how all four directories are being used in the overlay.
- The path after
onis the merged directory, which is the combined view that we interact with (/home/macc/overlayfs-lab/merged) - Inside the parentheses,
lowerdir=points to the lower directory, which contains the base read-only files (/home/macc/overlayfs-lab/lower) upperdir=points to the upper directory, where any changes or new files are stored (/home/macc/overlayfs-lab/upper)- Finally,
workdir=points to the work directory, which is used internally by the kernel to handle overlay operations (/home/macc/overlayfs-lab/work)
1.3.4 Inspect the merged view
ls ~/overlayfs-lab/merged/
cat ~/overlayfs-lab/merged/base_file.txt
Question 3: Can you see the files from the lower directory in the merged view? What does this tell you about how OverlayFS presents files to the user?
Answer:
Yes, I can see the files from the lower directory in the merged view.
$ ls ~/overlayfs-lab/merged/
base_file.txt  original.txt

$ cat ~/overlayfs-lab/merged/base_file.txt I am from the lower layer
This shows that OverlayFS combines the lower and upper directories into a single filesystem that looks unified to the user. Even though the lower directory is read-only, its files still appear normally in the merged view unless they are changed or overridden by something in the upper layer.
1.4 Part II: The Copy-on-Write Mechanism
This is the heart of OverlayFS. You will observe what actually happens to the underlying directories when you perform common file operations through the merged view.
1.4.1 Write a new file
echo "I was created in merged" > ~/overlayfs-lab/merged/new_file.txt
Now check all three visible directories:
ls ~/overlayfs-lab/lower/
ls ~/overlayfs-lab/upper/
ls ~/overlayfs-lab/merged/
Question 4: In which directory did new_file.txt appear? Was the lower directory affected? Explain why this behavior makes sense given OverlayFS's design.
Answer:
The file new_file.txt appeared in the upper directory, not in the lower one. The lower directory was not affected at all. This makes sense because OverlayFS uses a copy-on-write approach, so any new files or changes are stored in the upper layer while keeping the lower layer unchanged. The merged view just shows everything together, but all writes actually go to the upper directory.
$ echo "I was created in merged" > ~/overlayfs-lab/merged/new_file.txt

$ ls ~/overlayfs-lab/lower/
base_file.txt  original.txt

$ ls ~/overlayfs-lab/upper/
new_file.txt

$ ls ~/overlayfs-lab/merged/
base_file.txt  new_file.txt  original.txt
1.4.2 Modify a file that originated in the lower directory
echo "I have been modified" >> ~/overlayfs-lab/merged/base_file.txt
Check all three directories:
cat ~/overlayfs-lab/lower/base_file.txt
cat ~/overlayfs-lab/upper/base_file.txt
cat ~/overlayfs-lab/merged/base_file.txt
Question 5: What does each of the three cat commands output? Describe in detail what happened inside the filesystem when you appended to base_file.txt. This mechanism is called copy-on-write—why is that a fitting name?
Answer:
The lower directory still shows the original content:
$ cat ~/overlayfs-lab/lower/base_file.txt
I am from the lower layer
The upper directory now has a modified version of the file:
$ cat ~/overlayfs-lab/upper/base_file.txt
I am from the lower layer
I have been modified
The merged view shows the same modified version as the upper directory:
$ cat ~/overlayfs-lab/merged/base_file.txt
I am from the lower layer
I have been modified
What happened is that when I tried to modify base_file.txt through the merged view, OverlayFS didn't actually change the file in the lower directory. Instead, it copied the original file from the lower directory into the upper directory, and then applied the modification there. Then the merged view uses the version from the upper layer.
Since the file is only copied into the upper directory at the moment I try to modify it (i.e. writing it), instead of copying everything ahead of time, the name copy-on-write fits well. For example in the previous question, the upper directory only contained new_file.txt, since that was the only modification at that point, but now that we have modified an existing original file it was copied over and it now shows both base_file.txt and new_file.txt.
1.4.3 Delete a file from the merged view
rm ~/overlayfs-lab/merged/original.txt
Check all three directories:
ls -la ~/overlayfs-lab/lower/
ls -la ~/overlayfs-lab/upper/
ls ~/overlayfs-lab/merged/
Pay close attention to the output of ls -la ~/overlayfs-lab/upper/.
Question 6: Is original.txt still in the lower directory? Is it visible in the merged view? What unusual entry do you see in the upper directory? Run stat ~/overlayfs-lab/upper/original.txt and include the output. This special marker is called a whiteout—look up what a whiteout file is and explain its purpose in 2–3 sentences.
Answer:
Yes, original.txt is still in the lower directory, but it is no longer visible in the merged view. Instead, I see a strange entry in the upper directory: original.txt shows up as a character special file (c---------) owned by root.
$ ls -la ~/overlayfs-lab/lower/
total 16
drwxrwxr-x 2 macc macc 4096 Apr 22 02:16 .
drwxrwxr-x 6 macc macc 4096 Apr 22 02:09 ..
-rw-rw-r-- 1 macc macc   26 Apr 22 02:16 base_file.txt
-rw-rw-r-- 1 macc macc   22 Apr 22 02:16 original.txt

$ ls -la ~/overlayfs-lab/upper/
total 16
drwxrwxr-x 2 macc macc 4096 Apr 22 03:17 .
drwxrwxr-x 6 macc macc 4096 Apr 22 02:09 ..
-rw-rw-r-- 1 macc macc   47 Apr 22 03:07 base_file.txt
-rw-rw-r-- 1 macc macc   24 Apr 22 03:01 new_file.txt
c--------- 2 root root 0, 0 Apr 22 03:17 original.txt

$ ls ~/overlayfs-lab/merged/
base_file.txt new_file.txt
The output of stat ~/overlayfs-lab/upper/original.txt confirms this:
  File: /home/macc/overlayfs-lab/upper/original.txt
  Size: 0               Blocks: 0          IO Block: 4096   character special file
Device: 801h/2049d      Inode: 775743      Links: 2     Device type: 0,0
Access: (0000/c---------)  Uid: (    0/    root)   Gid: (    0/    root)
Access: 2026-04-22 03:17:19.128878041 +0000
Modify: 2026-04-22 03:17:19.128878041 +0000
Change: 2026-04-22 03:17:19.128878041 +0000
 Birth: 2026-04-22 03:17:19.128878041 +0000
This is called a whiteout file. A whiteout is a special marker that tells OverlayFS to hide a file that exists in the lower directory. Instead of actually deleting the file from the lower layer (which is read-only), OverlayFS creates this marker in the upper layer so the file is ignored in the merged view.
1.5 Part III: Layers Survive a Remount
One powerful property of OverlayFS is that the upper directory persists across unmounts, capturing all changes made during a session.
1.5.1 Unmount and remount
First, note down what is currently in the upper directory:
ls ~/overlayfs-lab/upper/
Unmount the overlay:
sudo umount ~/overlayfs-lab/merged
Check what is in the merged directory now:
ls ~/overlayfs-lab/merged/
Remount:
sudo mount -t overlay overlay -o lowerdir=/home/macc/overlayfs-lab/lower,upperdir=/home/macc/overlayfs-lab/upper,workdir=/home/macc/overlayfs-lab/work /home/macc/overlayfs-lab/merged
Check the merged view again:
ls ~/overlayfs-lab/merged/
cat ~/overlayfs-lab/merged/base_file.txt
Question 7: Did your changes from Part 2 survive the unmount and remount? Are they still present in the merged view? What does this imply about where the “state” of the overlay is actually stored?
Answer:
Yes, the changes from Part 2 survived the unmount and remount. After mounting again, new_file.txt was still there, original.txt was still hidden, and base_file.txt still showed the modified content. This means the state of the overlay is not stored in the merged directory itself, but in the upper directory. The merged view is just showing the combination of the lower layer and whatever state was saved in the upper layer.
$ ls ~/overlayfs-lab/upper/
base_file.txt  new_file.txt  original.txt

$ sudo umount ~/overlayfs-lab/merged
$ ls ~/overlayfs-lab/merged/
$ sudo mount -t overlay overlay -o ...

$ ls ~/overlayfs-lab/merged/
base_file.txt new_file.txt

$ cat ~/overlayfs-lab/merged/base_file.txt
I am from the lower layer
I have been modified
1.5.2 Starting fresh (resetting the upper layer)
One way to "undo" all changes is to simply clear the upper and work directories and remount:
sudo umount ~/overlayfs-lab/merged

rm -rf ~/overlayfs-lab/upper/* ~/overlayfs-lab/work/*

sudo mount -t overlay overlay -o lowerdir=/home/macc/overlayfs-lab/lower,upperdir=/home/macc/overlayfs-lab/upper,workdir=/home/macc/overlayfs-lab/work /home/macc/overlayfs-lab/merged

ls ~/overlayfs-lab/merged/

cat ~/overlayfs-lab/merged/base_file.txt
Question 8: What does the merged view look like now? Relate this to the concept of ephemeral containers in Docker — when a Docker container is deleted, what do you think happens to its upper layer?
Answer:
Now the merged view looks like the original state again, I only see base_file.txt and original.txt. And base_file.txt is back to its original content. All the changes I made before (like the new file, the modification, and the deletion) are gone.
$ ls ~/overlayfs-lab/merged/
base_file.txt  original.txt

$ cat ~/overlayfs-lab/merged/base_file.txt
I am from the lower layer
This happens because I cleared the upper and work directories, so there's no saved changes anymore. Relating this to Docker, it's similar to ephemeral containers, when a container is deleted, its upper layer (where all the changes happen) is also deleted. That means any changes made during the container’s lifetime are lost, and only the base image (lower layer) remains.
1.6 Part IV: Multiple Users, One Lower Layer
This part demonstrates the key scalability benefit of OverlayFS: many independent upper layers can share a single read-only lower layer.
1.6.1 Create two separate overlay mounts over the same lower directory
mkdir -p ~/overlayfs-lab/{upper_alice,work_alice,merged_alice}
mkdir -p ~/overlayfs-lab/{upper_bob,  work_bob,  merged_bob}
sudo mount -t overlay overlay -o lowerdir=/home/macc/overlayfs-lab/lower,upperdir=/home/macc/overlayfs-lab/upper_alice,workdir=/home/macc/overlayfs-lab/work_alice /home/macc/overlayfs-lab/merged_alice
sudo mount -t overlay overlay -o lowerdir=/home/macc/overlayfs-lab/lower,upperdir=/home/macc/overlayfs-lab/upper_bob,workdir=/home/macc/overlayfs-lab/work_bob /home/macc/overlayfs-lab/merged_bob
1.6.2 Make different changes in each
echo "Alice's private note" > ~/overlayfs-lab/merged_alice/alice_note.txt
echo "Alice's version"     >> ~/overlayfs-lab/merged_alice/base_file.txt

echo "Bob's private note"  > ~/overlayfs-lab/merged_bob/bob_note.txt
echo "Bob's version"       >> ~/overlayfs-lab/merged_bob/base_file.txt
1.6.3 Inspect isolation
ls ~/overlayfs-lab/merged_alice/
ls ~/overlayfs-lab/merged_bob/
cat ~/overlayfs-lab/merged_alice/base_file.txt
cat ~/overlayfs-lab/merged_bob/base_file.txt
cat ~/overlayfs-lab/lower/base_file.txt
Question 9: Can Alice see Bob's files, or vice versa? What is the state of base_file.txt in the lower directory after both Alice and Bob modified it in their respective views? What does this demonstrate about OverlayFS isolation?
Answer:
No, Alice and Bob cannot see each other’'s files. Alice only sees alice_note.txt and her version of base_file.txt, while Bob only sees bob_note.txt and his own version of base_file.txt.
$ ls ~/overlayfs-lab/merged_alice/
alice_note.txt  base_file.txt  original.txt

$ ls ~/overlayfs-lab/merged_bob/
base_file.txt  bob_note.txt  original.txt

$ cat ~/overlayfs-lab/merged_alice/base_file.txt
I am from the lower layer
Alice's version

$ cat ~/overlayfs-lab/merged_bob/base_file.txt
I am from the lower layer
Bob's version
The base_file.txt in the lower directory is still unchanged and only contains the original content:
$ cat ~/overlayfs-lab/lower/base_file.txt
I am from the lower layer
This shows that each user has their own independent upper layer, so their changes don't affect each other or the lower layer. OverlayFS keeps everything isolated while still sharing the same base files.
Question 10: Suppose you are building a system that needs to give 500 students each an isolated Linux environment with the same base OS. How would OverlayFS help you do this efficiently, compared to giving each student a full copy of the OS? What is stored once, and what is stored per student?
Answer:
OverlayFS would make this way more efficient because I wouldn't need to copy the entire OS 500 times. Instead, I can keep a single shared lower directory with the base OS that all students use. Then, each student gets their own upper directory where their personal changes, files, and modifications are stored.
So basically, the base OS is the one that is stored once, and only the differences (like installed programs or new/modified files) are stored per student. This saves a lot of disk space and makes it much faster to set up, since I'm not technically duplicating the whole system for everyone.
1.7 Part V: Cleanup (always do this!)
Leaving overlay mounts around can cause confusion. Clean up when done:
sudo umount ~/overlayfs-lab/merged_alice
sudo umount ~/overlayfs-lab/merged_bob
sudo umount ~/overlayfs-lab/merged   2>/dev/null || true
rm -rf ~/overlayfs-lab/
Verify no overlay mounts remain:
mount | grep overlay
Question 11: Why is it important to unmount filesystems before deleting their backing directories? What might go wrong if you deleted the upper directory while the overlay was still mounted?
Answer:
It's important to unmount first because the filesystem is still actively using those directories while it's mounted. If we delete something like the upper directory while the overlay is still mounted, the kernel might still try to read/write to it, which I understand can cause errors or unpredictable behavior.
For example, in a bad case I could even corrupt data or leave the system in an inconsistent state where the overlay is pointing to something that no longer exists. So unmounting first basically makes sure everything is cleanly disconnected before deleting anything.
1.8 Part VI: Reflection
Question 12: Docker uses OverlayFS as its default storage driver. Based on what you observed in this lab, describe in 3–5 sentences how Docker likely uses the lower, upper, and merged directories when you run a container from an image. What corresponds to the “image” and what corresponds to the “running container”?
Answer
No wonder Docker relies on OverlayFS as its default storage driver, it fits really well with what Docker is trying to do. A Docker "image" corresponds to the lower directory, which acts as a read-only base that can be shared across many containers. Each running container then gets its own upper and work directories, where any changes, new files, or modifications are stored. The merged directory is what the container actually sees, combining the base image with its own changes. This way, each container behaves like its own isolated environment while only storing the differences from the original image.
2. Regular Expressions
2.1 History of Regular Expressions
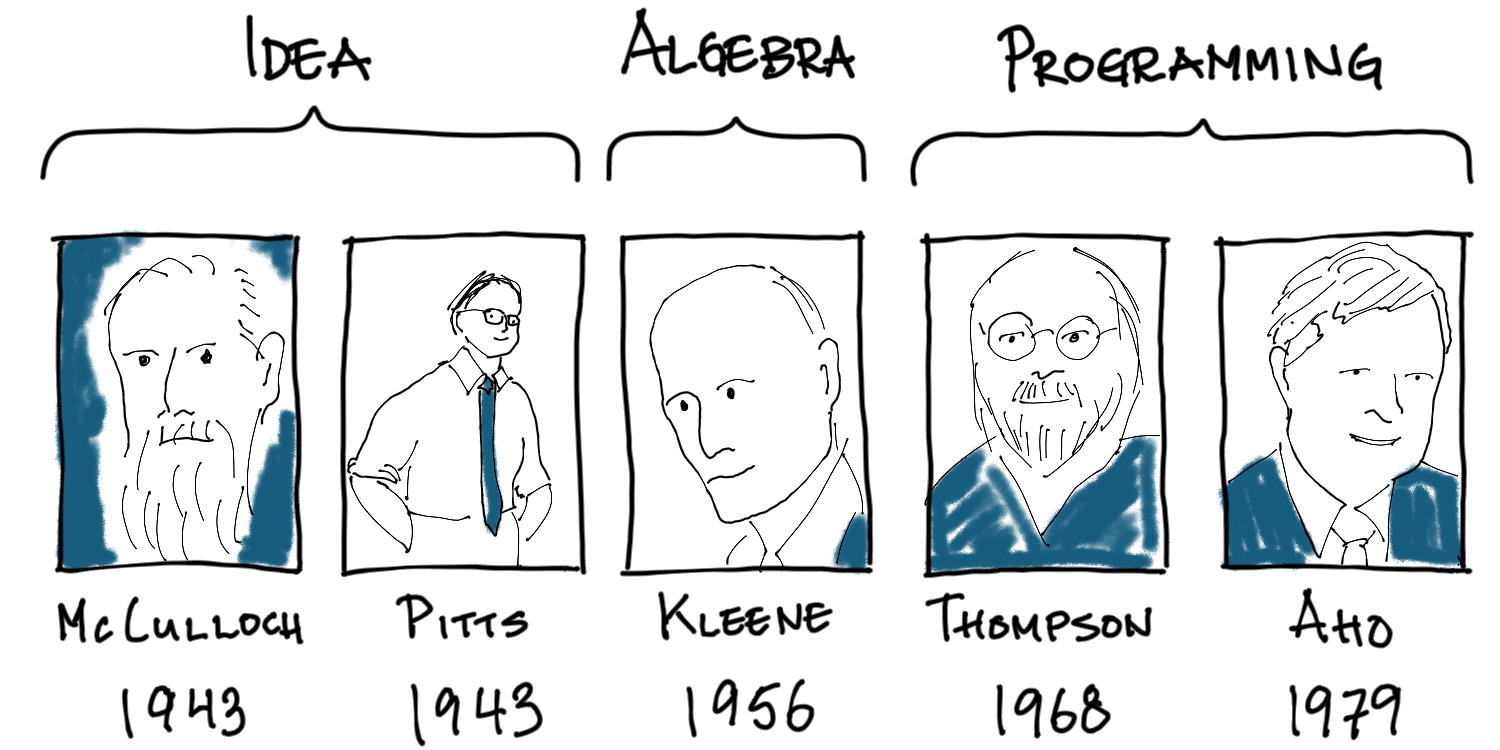
Regular expressions is a programming language with which we can specify a set of strings. Supported by only two operations and one function, we can be very concise. A non-concise alternative would be to list all the strings included in the set. Where does this regular expressions language come from?
A historical perspective:
The story begins with a neuroscientist and a logician who together tried to understand how the human brain could produce complex patterns using simple cells that are bound together.
In 1956, mathematician Stephen Kleene took McCulloch and Pitts' theories one step further. Kleene presented a simple algebra, and somewhere along the line, the terms regular sets and regular expressions were born.
In 1968, Unix pioneer Ken Thompson published “Regular Expression Search Algorithm” in Communications of the ACM. With code and prose, he described a regular expression compiler that created IBM 7094 object code. He also implemented Kleene’s notation in the editor QED. The value was that users could do advanced pattern matching in text files.
2.2 Complete a regex tutorial
Complete this regex tutorial (Regex 101—EN) and submit a screenshot of the web page which shows that you've completed all exercises. You will be tested on it in the exam.
What is Regular Expressions Regex?
Regular Expressions are a string of characters that express a search pattern. Often abbreviated as Regex or Regexp. It is especially used to find or replace words in texts. In addition, we can test whether a text complies with the rules we set.
For example, let's say you have a list of filenames. And you only want to find files with the pdf extension. Following typing an expression ^\w+\.pdf$ will work. The meaning of the definitions in this expression will become clearer as the steps progress.
Basic Matchers
Character/word
The character or word we want to find is written directly. It is similar to a normal search process. For example, to find the word curious in the text, type the same.
Dot .: Any Character
The period . allows selecting any character, including special characters and spaces.
abcABC123 .:!?
Character Sets [abc]
If one of the characters in a word can be various characters, we write it in square brackets [] with all alternative characters. For example, to write an expression that can find all the words in the following text, type the characters a, e, i, o, u adjacently within square brackets [].
Text:
bar ber bir bor bur
Regex:
b[aeiou]r
Negated Character Sets [^abc]
To find all words in the text below, except for ber and bor, type e and o side by side after the caret ^ character inside square brackets [].
Text:
bar bir bur
Regex:
b[^eo]r
Letter Range [a-z]
To find the letters in the specified range, the starting letter and the ending letter are written in square brackets [] with a dash between them -. It is case-sensitive. Type the expression that will select all lowercase letters between e and o, including themselves.
Text:
efghijklmno
Regex:
[e-o]
Number Range [0-9]
To find the numbers in the specified range, the starting number and the ending number are written in square brackets [] with a dash - between them. Write an expression that will select all numbers between 3 and 6, including themselves.
Text:
3456
Regex:
[3-6]
Practice I
Write the expression that will select the words of in the text.
Text:
“Every man takes the limits of his own field of vision for the limits of the world.”
― Arthur Schopenhauer
Regex:
of
Type the expression to select individual letters, numbers, spaces, and special characters in the text. The expression you type must match any character.
Regex:
.
Write the phrase that matches each word in the text. The only characters that change are the initials of the words.
Text:
beer deer feer
Regex:
[bdf]eer
Write down the expression that will match anything other than the words beor and beur in the text. Do this using the negated character set.
Text:
bear beor beer beur
Regex:
be[^ou]r
Write the expression that will select the letters from g to k in the text.
g and k letters should also be included in this range.
Text:
abcdefghijklmnopqrstuvwxyz
Regex:
[g-k]
Type an expression to select numbers from 2 to 7 in the text.
2 and 7 should also be included in this range.
Text:
0123456789
Regex:
[2-7]
Repetitions
Some special characters are used to specify how many times a character will be repeated in the text. These special characters are the plus +, the asterisk *, and the question mark ?.
Asterisk *
We put an asterisk * after a character to indicate that the character may either not match at all or can match many times. For example, indicate that the letter e should never occur in the text, or it can occur once or more side by side.
Text:
br ber beer
Regex:
be*r
Plus Sign +
To indicate that a character can occur one or more times, we put a plus sign + after a character. For example, indicate that the letter e can occur one or more times in the text.
Text:
ber beer
Regex:
be+r
Question Mark ?
To indicate that a character is optional, we put a ? question mark after a character. For example, indicate that the following letter u is optional.
Text:
color colour
Regex:
colou?r
Curly Braces - 1
To express a certain number of occurrences of a character, at the end we write curly braces {n} along with how many times we want it to occur. For example, indicate that the following letter e can occur only 2 times in a row.
Text:
beer
Regex:
be{2}r
Curly Braces - 2
To express at least a certain number of occurrences of a character, immediately after the character we write at least how many times we want it to occur in a row followed by a comma , and wrapped inside curly braces {n, }. For example, indicate that the following letter e can occur at least 3 times in a row.
Text:
beeer beeeer
Regex:
be{3,}r
Curly Braces - 3
To express the occurrence of a character in a certain number range, we write curly braces {x,y} for the inclusive interval. For example, indicate that the following letter e can only occur between 1 and 3 times in a row.
Text:
ber beer beeer
Regex:
be{1,3}r
Grouping
Parentheses ()
We can group an expression and use these groups to reference or enforce some rules. To group an expression, we enclose () in parentheses. For now just group haa below.
Text:
haa-haa
Regex:
(haa)
Referencing a Group
Below, we have two groups: (ha) and (haa). When we want to reference these groups later in the pattern, we use \1 for the first group and \2 for the second group. For example, in the pattern (ha)-\1,(haa)-\2, the - is outside the groups, and \1 refers to ha while \2 refers to haa. Type \2 at the end of the expression to refer to the second group.
Text:
ha-ha,haa-haa
Regex:
(ha)-\1,(haa)-\2
Parentheses (?:): Non-capturing Grouping
You can group an expression and ensure that it is not captured by references. For example, below are two groups. However, the first group reference we denote with \1 actually indicates the second group, as the first is a non-capturing group.
Text:
ha-ha,haa-haa
Regex:
(?:ha)-ha,(haa)-\1
Pipe Character |
It allows to specify that an expression can be in different expressions. Thus, all possible statements are written separated by the pipe sign |. This differs from charset [abc], charsets operate at the character level. Alternatives are at the expression level. For example, the following expression would select both cat and rat. Add another pipe sign | to the end of the expression and type dog so that all words are selected.
Text:
cat rat dog
Regex:
(c|r)at|dog
Escape Character \
There are special characters that we use when writing regex. { } [ ] / \ + * . $^ | ? Before we can select these characters themselves, we need to use an escape character \. For example, to select the dot . and asterisk * characters in the text, let's add an escape character \ before it.
Text:
(*) Asterisk.
Regex:
(\*|\.)
- Only selects
*and.
Caret Sign ^: Selecting by Line Start
We were using [0-9] to find numbers. To find only numbers at the beginning of a line, prefix this expression with the ^ sign.
Text:
Basic Omellette Recipe

1. 3 eggs, beaten
2. 1 tsp sunflower oil
3. 1 tsp butter
Regex:
^[0-9]
- Only selects
1,2, and3at the beginning of the line
Dollar Sign $: Selecting by End of Line
Let's use the $ sign after the html value to find the html texts only at the end of the line.
Text:
https://domain.com/what-is-html.html
https://otherdomain.com/html-elements
https://website.com/html5-features.html
Regex:
html$
- Only selects first and third line
Word Character \w: Letter, Number and Underscore
The expression \w is used to find letters, numbers and underscore characters. Let's use the expression \w to find word characters in the text.
Text:
abcABC123 _.:!?
Regex:
\w
- Only selects
abcABC123 _
Except Word Character \W
The expression \W is used to find characters other than letters, numbers, and underscores.
Text:
abcABC123 _.:!?
Regex:
\W
- Only selects
.:!?(including space)
Number Character \d
\d is used to find only number characters.
Text:
abcABC123 .:!?
Regex:
\d
- Only selects
1,2, and3
Except Number Character \D
\D is used to find non-numeric characters.
Text:
abcABC123 .:!?
Regex:
\D
- Only selects
abcABC .:!?
Space Character \s
\s is used to find only space characters.
Text:
abcABC123 .:!?
Regex:
\s
- Only selects
Except Space Character \S
\S is used to find non-space characters.
Text:
abcABC123 .:!?
Regex:
\S
- Only selects
abcABC123.:!?(not including blank space)
Lookarounds
If we want the phrase we're writing to come before or after another phrase, we need to "lookaround".
Positive Lookahead: (?=)
For example, we want to select the hour value in the text. Therefore, to select only the numerical values that have PM after them, we need to write the positive look-ahead expression (?=) after our expression. Include PM after the '=' sign inside the parentheses.
Text:
Date: 4 Aug 3PM
Regex:
\d+(?=PM)
- Only selects
3
Negative Lookahead: (?!)
For example, we want to select numbers other than the hour value in the text. Therefore, we need to write the negative look-ahead (?!) expression after our expression to select only the numerical values that do not have PM after them. Include PM after the ! sign inside the parentheses.
Text:
Date: 4 Aug 3PM
Regex:
\d+(?!PM)
- Only selects
4
Positive Lookbehind: (?<=)
For example, we want to select the price value in the text. Therefore, to select only the number values that are preceded by $, we need to write the positive lookbehind expression (?<=) before our expression. Add \$ after the = sign inside the parenthesis.
Regex in this step is not supported by some browsers.
Text:
Product Code: 1064 Price: $5
Regex:
(?<=\$)\d+
- Only selects
5
Negative Lookbehind: (?<!)
For example, we want to select numbers in the text other than the price value. Therefore, to select only numeric values that are not preceded by $, we need to write the negative lookbehind (?<!) before our expression. Add \$ after the ! inside the parenthesis.
Regex in this step is not supported by some browsers.
Text:
Product Code: 1064 Price: $5
Regex:
(?<!\$)\d+
- Only selects
1064
Flags
Flags change the output of the expression. That's why flags are also called modifiers. Flags determine whether the typed expression treats text as separate lines, is case sensitive, or finds all matches.
Global Flag:
The global flag causes the expression to select all matches. If not used it will only select the first match. Now enable the global flag to be able to select all matches.
Text:
domain.com, test.com, site.com
Regex:
/\w+\.com/g
- Selects
domain.com,test.com, andsite.com
Multiline Flag
Regex sees all text as one line. But we use the multiline flag to handle each line separately. In this way, the expressions we write to identify patterns at the end of lines work separately for each line. Now enable the multiline flag to find all matches.
Text:
domain.com
test.com
site.com
Regex:
/\w+\.com$/gm
Case-insensitive Flag
In order to remove the case-sensitivity of the expression we have written, we must activate the case-insensitive flag.
Text:
DOMAIN.COM
TEST.COM
SITE.COM
Regex:
/\w+\.com$/gmi
Greedy Matching
Regex does a greedy match by default. This means that the matching will be as long as possible. Check out the example below. It refers to any match that ends in r and can be any character preceded by it. But it does not stop at the first match.
Text:
ber beer beeer beeeer
Regex:
.*r
Lazy Matching
Lazy matching, unlike greedy matching, stops at the first matching. For example, in the example below, add a ? after * to find the first match that ends with the letter r and is preceded by any character. It means that this match will stop at the first letter r.
Text:
ber beer beeer beeeer
Regex:
.*?r
2.3 Simple regex matches
Consider the following text:
You can start the playlist with the links below. Each codelab provides
23 , 45,56, 98 step-by-step instructions to guide you through the
A123-45-6789 lesson. foo Once you finish a codelab,
you can move on to the next one in the list. Start with the first
codelab, "Fundamentals of Apps Script with Google Sheets #1: Macros &
Custom Functions".
What strings in the text will be matched by the following regular expressions? For each regexp below, give a very brief description of what the regexp matches. Because there are many different representations of regular expressions, we will focus on the PCRE version. You can use the website https://regexr.com/ to confirm your understanding of the matches for each regular expression.
prov.*^\w\d+<a\s*\w+=.*>[123]+[,]\W{2}^[\d-]+\w+,$li\w*
Answer:
1. prov.*
- Matches (1):
provides - This matches
provfollowed by any characters after it on the same line. In this text, it starts atprovin provides and matches the rest of that word.
2. ^\w\d+
- No match.
- This looks at the start of the text, followed by one word character and then one or more digits. The text starts with
You, so this pattern does not match anything.
3. <a\s*\w+=.*>
- No match.
- Tries to match something that looks like an HTML tag starting with
<a, followed by spaces (optional), an attribute,'=', and then more text until>. There is nothing like that in the given text, not even a<or>sign.
4. [123]+
- Matches (3):
23,123, and1 - This matches one or more occurrences of the digits
1,2, or3in a row. Written as a character set so that any occurrence of them can match (not necessarily exactly123)
5. [,]\W{2}
- Matches (1):
, " - This matches a comma
,followed by exactly two non-word and non-digit characters.
6. ^[\d-]+
- No match.
- This looks for the start of the whole text followed by one or more digits or hyphens. Since the text starts with
You, there is no match.
7. \w+,$
- No match.
- This would match one or more word/digit characters followed by a comma at the very end of the whole text. The text does not end that way, so there is no match.
8. li\w*
- Matches (3):
list(from play'list'),links, andlist - This matches
lifollowed by zero or more word/digit characters, so it finds words that begin withli.
2.4 Find all matches in a messy systems log
Use PCRE-style regular expressions to analyze the following text block:
port 22 open, port 2222 closed, user_a logged-in, user-b failed, pid=7812, pid=42, tmp.tar.gz, notes.txt, ERR_CONN_RESET
For each of the following regexes, list every match and give a one-sentence description of what it matches:
port\s\d+
\bpid=\d{2,4}\b
\b\w+\.txt\b
[A-Z_]{3,}
user[-_]?[A-Za-z]+
Submit
- The full list of matches for each regex.
- A short description for each regex.
- A note on one regex that might surprise students and why.
Suggested references:
Answer:
1. port\s\d+
- Matches (2):
port 22port 2222
- This matches the word
port, followed by a whitespace character, and then one or more digits.
2. \bpid=\d{2,4}\b
- Matches (2):
pid=7812pid=42
- This matches
pid=followed by a number that is between 2 and 4 digits long, with word boundaries so it matches as a complete string.
3. \b\w+\.txt\b
- Matches (1):
notes.txt
- This matches a whole word made of one or more word/digit characters, followed by
.txt, so it is able to find.txtfilenames.
4. [A-Z_]{3,}
- Matches (1):
ERR_CONN_RESET
- This matches any sequence of uppercase letters or underscores that are at least 3 characters long.
5. user[-_]?[A-Za-z]+
- Matches (2):
user_auser-b
- This matches strings starting with
user, optionally followed by either-or_, and then one or more lowercase or uppercase letters.
6. regex that might surprise students
- The regex from this set that may be surprising at some point is the 3rd one:
\b\w+\.txt\b, because at first it may seem like it could match any.txtfile name but in fact it does not. Because\wonly matches word characters (i.e. letters, digits,_), so it works fornotes.txtbut would not fully match something likefile-name.txtsince the hyphen is not included in the\wgroup.
2.5 Write a stricter validator
Write one regex that matches course repository names of the form
csce313-labN-netid
where YYYY-MM-DD_error.log where the year is 2025 or 2026. Give at least four strings that should match and four that should not for each regex.
Students should submit:
- The two final regexes.
- Positive and negative test cases for each regex.
- One or two sentences explaining how anchors helped you make the regex strict.
Answer:
1. Regex for course repository names
^csce313-lab[0-9]-[a-z]{3,8}$
- Note: I enabled the
gmflag (global + multiline flag) so that matching strings in separate lines are all matched - I intentionally ignored matching strings in the same line or lines with a matching string and non-matching content, since that would break the end anchor and instructions did not specified about this.
Positive test cases:
csce313-lab0-max
csce313-lab1-mxmarin
csce313-lab2-abcdefgh
csce313-lab3-socket
Negative test cases:
csce313-lab10-max
csce313-lab4-MAX
csce313-lab5-ab
mycsce313-lab6-abcdefghi
2. Regex for log file names
^(2025|2026)-[0-9]{2}-[0-9]{2}_error\.log$
- Note: I enabled the
gmflag (global + multiline flag) so that matching strings in separate lines are all matched - Similar to regex 1, I intentionally ignored matching strings in the same line or lines with a matching string and non-matching content, since that would break the end anchor and instructions did not specified about this.
Positive test cases:
2025-01-01_error.log
2025-12-31_error.log
2026-04-18_error.log
2026-10-31_error.log
Negative test cases:
2024-04-18_error.log
2027-04-18_error.log
2026-4-18_error.log
2025-04-18_error.txt
3. Anchors
The ^ and $ anchors make the regex strict by forcing the whole string to match the pattern from beginning to end. They avoids matching long strings that may contain a matching section or malformed lines with different matching string in a single line. Without anchors, the regex could still match just part of a longer invalid string, which would make it less precise.
2.6 Greedy, lazy, and grouped matches
Given the text,
<msg id=7>alpha</msg><msg id=8>beta gamma</msg><msg id=9>x</msg>
compare the matches produced by each of the following regular expressions.
<msg.*</msg>
<msg.*?</msg>
<msg\s+id=(\d+)>(.*?)</msg>
Explain how greediness changes the result and identify which capturing groups would be returned by the third regex for every match. Submit
- The exact match set for all three regexes.
- The capture-group values returned by the third regex.
- A short explanation of greedy versus lazy behavior in this example.
Answer:
1. <msg.*</msg>
- Note: technically this regex is broken because
/is a special character treated as a delimiter, we have to scape it in order to match it. So I will instead consider:<msg.*<\/msg> - Match set (1):
<msg id=7>alpha</msg><msg id=8>beta gamma</msg><msg id=9>x</msg>
- The
.*is greedy, so it matches as much as possible while still allowing the regex to end with</msg>. That means it starts at the first<msgand keeps going all the way to the last</msg>in the string, making it a single big match.
2. <msg.*?</msg>
- Note: again I escaped the
/character and instead considered:<msg.*?<\/msg> - Match set (3):
<msg id=7>alpha</msg><msg id=8>beta gamma</msg><msg id=9>x</msg>
- Here
.*?is lazy (non-greedy), so it matches as little as possible before stopping at the first</msg>it can use. That makes it match each matching string separately.
3. <msg\s+id=(\d+)>(.*?)</msg>
- Note: again I escaped the
/character and instead considered:<msg\s+id=(\d+)>(.*?)<\/msg> - Match set with capture groups (3):
<msg id=7>alpha</msg>- Group 1:
7 - Group 2:
alpha
- Group 1:
<msg id=8>beta gamma</msg>- Group 1:
8 - Group 2:
beta gamma
- Group 1:
<msg id=9>x</msg>- Group 1:
9 - Group 2:
x
- Group 1:
- This also produced 3 separate matches because we are using
.*?(lazy matching). The only difference is that we are making the regex more strict in what can be inside the starting<msg>label.
Greedy vs lazy behavior:
In this example, a greedy pattern like .* grabs as much text as it is able to, so <msg.*</msg> ends up consuming everything from the first <msg to the last </msg>. A lazy pattern like .*? grabs as little as possible, so it stops at the first valid </msg>, matching each <msg>...</msg> block separately. That is why the second and third regex split the text into three individual matches instead of one big string.
3 SSH Reverse Tunneling
Note that outside of this assignment, you need to check if setting up reverse tunnels is a violation of TAMU's Network Policy. You are responsible for adhering to that policy. This assignment just exposes you to the possibilities of setting up reverse tunnels that are useful, such as forwarding X traffic from applications running outside your local network to your laptop display.
In this task you will learn why SSH reverse tunneling is useful and how to setup reverse tunneling. It's useful particularly in scenarios where direct access to a remote machine (which could be your local machine if you're behind a firewall) is restricted.
For this assignment, you'll make a forward ssh connection from your laptop to your GCP VM, but reverse tunnel from a port on the GCP VM to a web server running on your laptop. What the reverse tunnel enables you to do is advertise a publicly available service on your GCP VM but tunnel all inbound TCP connection to that service to the actual service running on your laptop. That picture looks like this.
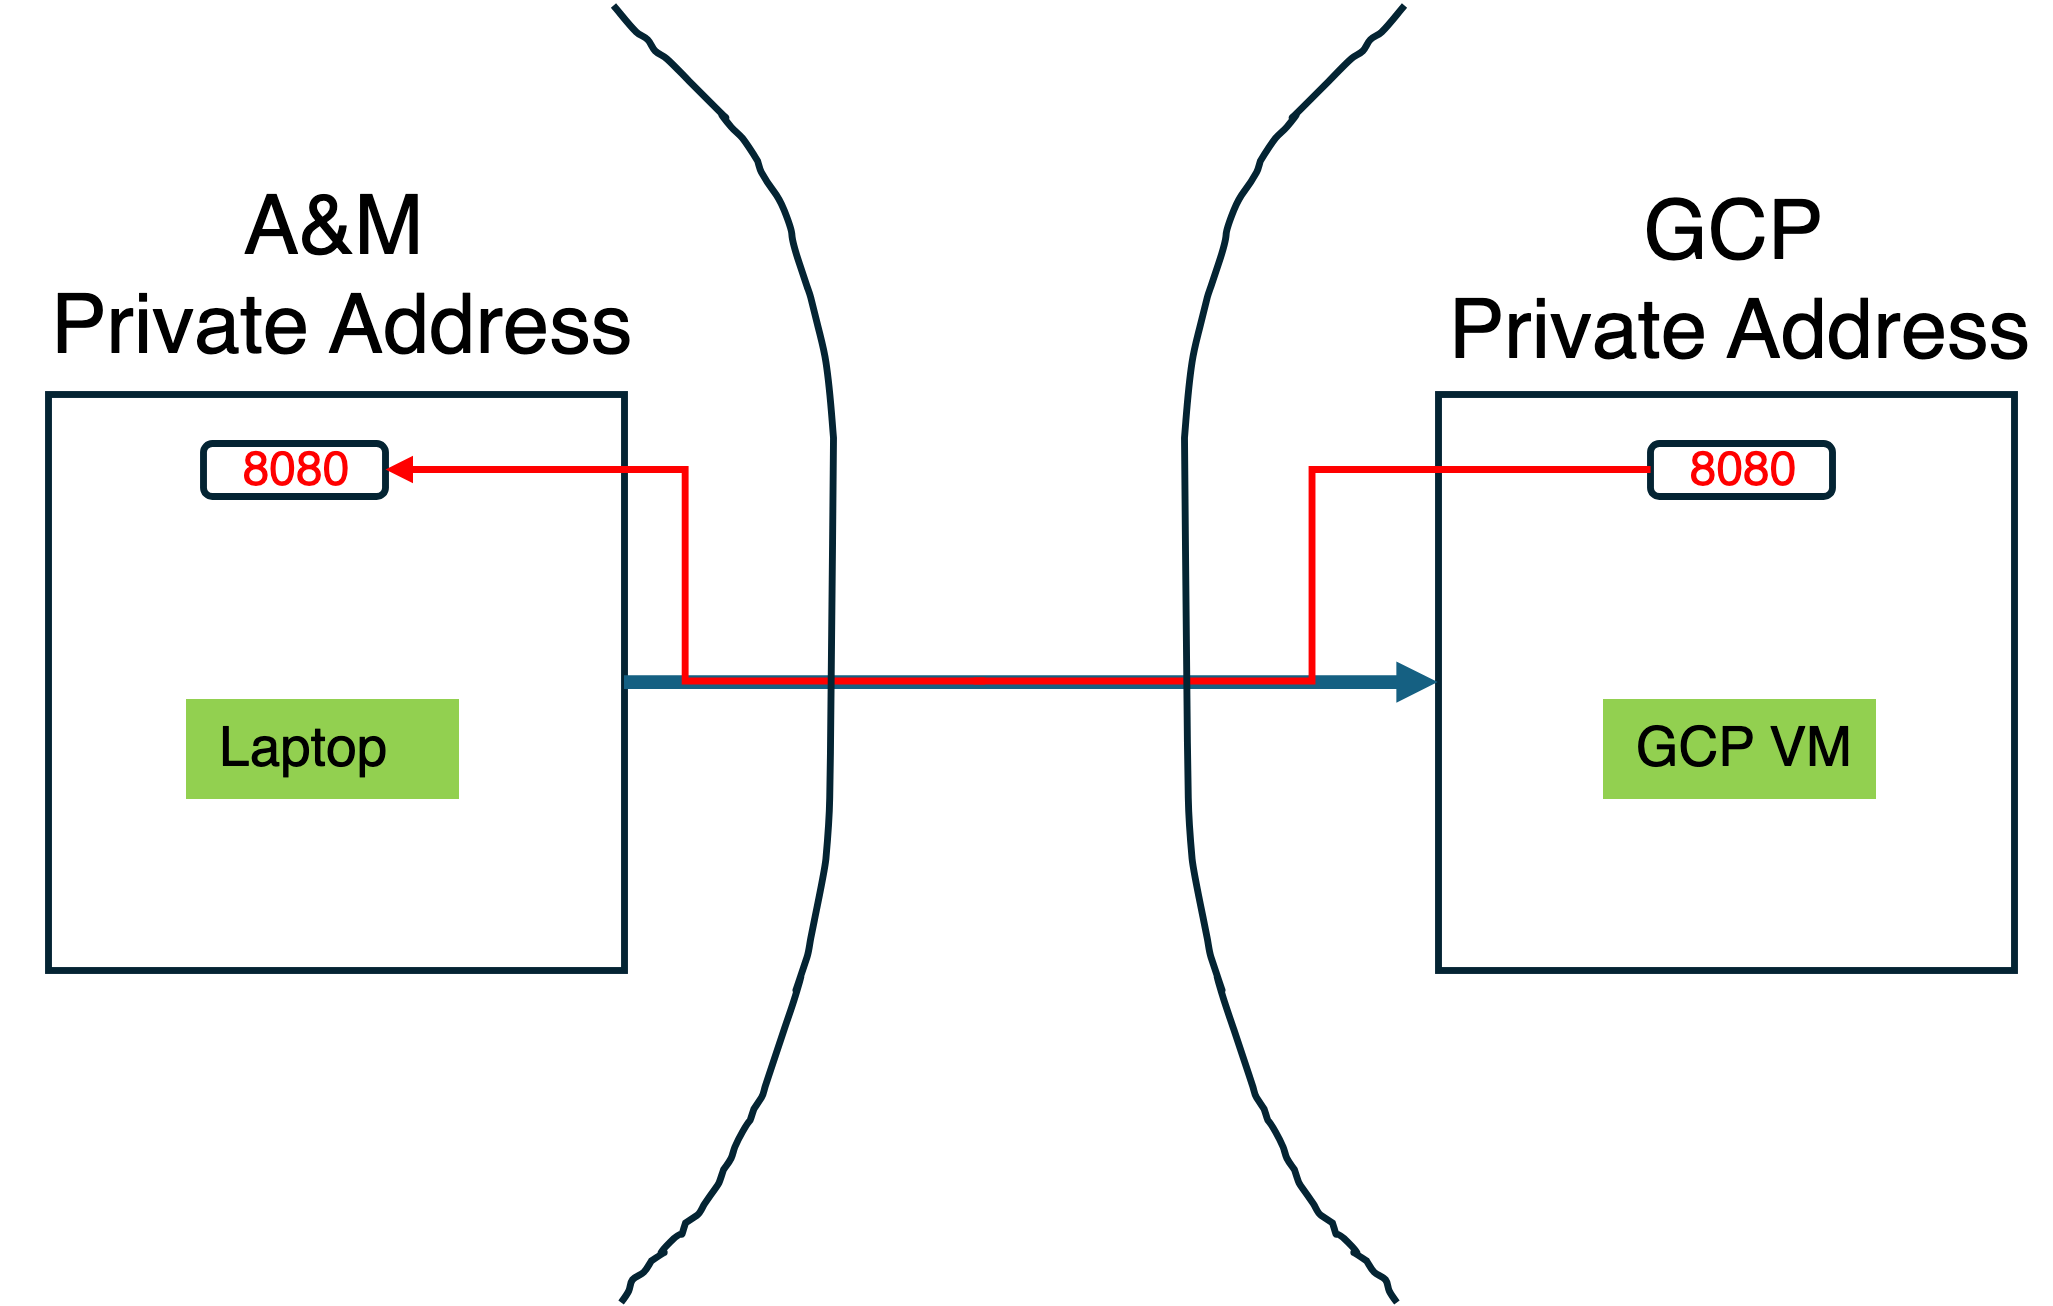
The following resources may be helpful.
- https://jfrog.com/connect/post/reverse-ssh-tunneling-from-start-to-end/.
- The man pages of ssh.
For e.g., your IP address inside the TAMU network is most likely a non-routable IP address and cannot be reached directly from the outside. Given that constraint, have you ever needed to access your laptop from the “outside”?
Similarly, your ISP at home may assign you a non-routable IP address when you connect to the Internet from home. Is there a way that you can ssh into your machine at home from TAMU? You will set up an SSH reverse tunnel to securely access a service running on your laptop machine, demonstrating your understanding of how to use reverse tunneling in practical situations.
3.1 Instructions
Big picture
-
Set up a web service on your laptop. Run a simple web server (such as
nginx) on port 8080 of your laptop. You can use any web server or even a simple Python HTTP server such as the following.python3 -m http.server 8080 -
Create a reverse tunnel that exposes the web server running on your laptop at port 8080 on your GCP VM. Once the reverse tunnel is set up, download a file on your GCP VM from your laptop using a command such as
wget http://localhost:8080/foo
- your laptop runs the web server on port
8080 - your laptop starts an SSH connection to the GCP VM
- that SSH connection creates a reverse tunnel, so a port on the VM points back to your laptop’s port
8080
Detailed instructions
What reverse tunneling means
Normally, if you do plain SSH:
ssh user@your-vm
- your laptop connects to the VM.
With a reverse tunnel, you still connect from laptop to VM, but you also tell SSH:
- "Please open a port on the VM, and whenever something connects there, send that traffic back through this SSH connection to my laptop."
- That is exactly what this assignment wants.
Step 0: Make sure we have a file to serve
On your Mac, make a test directory and file:
mkdir -p ~/reverse-tunnel-test
cd ~/reverse-tunnel-test
echo "hello from my laptop" > foo
This gives you a file called foo that the web server can serve.
Step 1: Start a web server on your Mac
Still on your Mac, inside that directory, run:
python3 -m http.server 8080
Serving HTTP on :: port 8080 ]:8080/ ...
- That starts a simple HTTP server on port 8080.
- We need to leave this terminal running
Step 2: Verify the web server works locally on your Mac
Open another terminal on your Mac and test:
curl http://localhost:8080/foo
You should get:
hello from my laptop
Step 3: Make sure you can SSH from your Mac into the GCP VM
Test your normal SSH access:
ssh your_username@your_vm_external_ip
Step 4: Create the reverse tunnel
Now run this from your Mac:
ssh -R 8080:localhost:8080 your_username@your_vm_external_ip
What this means
The important part is:
-R 8080:localhost:8080
- This means:
- open port
8080on the remote machine (the VM) - forward any connections from there to
localhost:8080on the client side of the SSH connection, which is your Mac
- open port
- So:
- left side
8080= port on the VM - right side
localhost:8080= your Mac's local web server
- left side
That SSH session must stay open while the tunnel is active.
Step 5: Test it from the VM
Once that SSH session is active, either:
- use that same session after logging in, or
- open a second SSH window into the VM
Then on the VM, run:
wget http://localhost:8080/foo
If everything is working, the VM should retrieve:
hello from my laptop
That proves the VM’s port 8080 is tunneling back to your laptop.
- When the VM runs:
wget http://localhost:8080/foo- the request goes to port
8080on the VM.
- the request goes to port
- But because of the reverse tunnel, SSH intercepts that traffic and sends it back through the encrypted SSH session to your Mac, where your Python web server answers it.
- So the VM looks like it has the service locally, but the service is actually running on your laptop.
Difference between reverse and forward tunneling
- Local/forward tunnel:
ssh -L local_port:target_host:target_port user@remote- This opens a port on your laptop that points to something on the remote side.
- Reverse tunnel
ssh -R remote_port:target_host:target_port user@remote- This opens a port on the remote machine that points back to something on your laptop.
FYI Tip
What ~/.ssh/config is
- It’s a config file on your laptop that lets you save SSH settings (like host, key, and port forwarding) so you don’t have to type them every time.
Instead of running a long command like:
ssh -i ~/.ssh/my_key -L 5432:localhost:5432 your_username@your_vm_external_ip
you can define it once in:
~/.ssh/config
How you would set it up
On your Mac, open or create:
nano ~/.ssh/config
Add something like this:
Host my-vm
    HostName your_vm_external_ip
    User your_username
    IdentityFile ~/.ssh/my_key
    LocalForward 5432 localhost:5432
What each line means
Host my-vm→ shortcut name you’ll useHostName→ actual VM IPUser→ your username on the VMIdentityFile→ your SSH key (if you use one)LocalForward 5432 localhost:5432→ same as-L 5432:localhost:5432
How you use it after that
Now instead of the long command, you just run:
ssh my-vm
And it will:
- connect to the VM
- automatically set up the port forwarding
3.2 Answer the following
1. What is the command you used to establish the reverse tunnel? You may also want to find out how to set this option in ~/.ssh/config, but we won't expect you to know it for the purpose of this class.
Answer:
The command I used to established the reverse tunnel is:
ssh -R 8080:localhost:8080 macc@136.112.29.231
- where
maccis my user for my GCP VM and136.112.29.231is the external IP exposed for my GCP VM.
The option: -R 8080:localhost:8080 means
- open port
8080on the the VM (remote machine) - forward any connections from there to
localhost:8080on the client side of the SSH connection, which is my laptop
2. How does SSH reverse tunneling work in this scenario. Briefly explain what's happening in terms of network connections.
Answer:
In this setup, my laptop first makes a normal SSH connection to the GCP VM, so the connection is initiated from inside my network. When I add the -R option, SSH tells the VM to open a port (i.e. 8080) and forward anything that connects to it back through that same SSH connection to my laptop.
So when I run something like wget http://localhost:8080/foo on the VM, it looks like it's accessing a local service, but the request actually travels through the SSH tunnel back to my laptop, where the web server is running. The response then goes back through the same tunnel to the VM. Basically, the VM is acting like a public entry point, while the actual web server is actually running on my laptop.
3. Why is port 8080 on the GCP VM able to access port 8080 on your laptop?
Answer:
Port 8080 on the GCP VM is able to access port 8080 on my laptop because of the reverse tunnel I set up with SSH. When I used the -R option, it basically told the VM to take any traffic that comes into its local port 8080 and send it through the SSH connection back to my laptop's port 8080. So even though the VM and my laptop are on completely different networks, the SSH connection acts like a bridge between them. That's the reason why something running on the VM can access my local web server as if it were running there.
4. Provide a screenshot of the successful fetch of file foo using the wget command.
Answer:
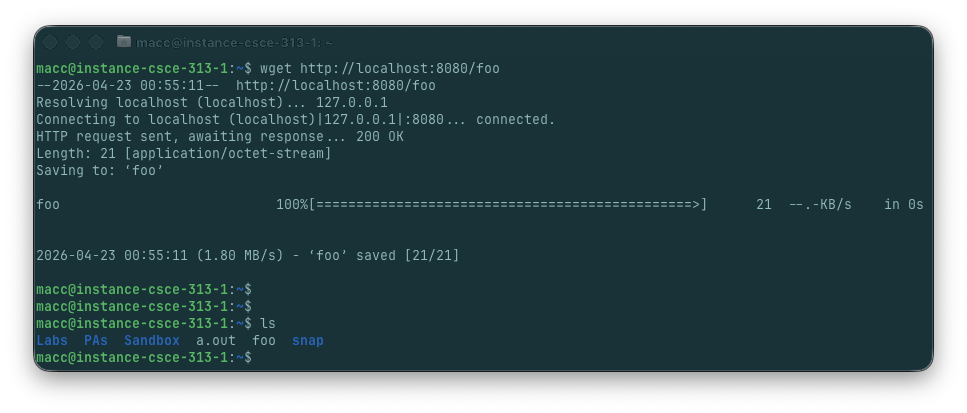
5. How can you do the opposite—i.e., connect to a port on your laptop and have the connection tunnel to a port on your GCP VM? Write the command for doing it. Again, you may also want to figure out how to do this with ~/.ssh/config.
Specifically, let's say that a service is listening on localhost:5432 on your VM and you want to access it safely from your laptop without exposing it publicly (i.e., not exposing the service to other VMs). Write the SSH command that creates the tunnel, show how you would connect to the forwarded port from your laptop, and explain why binding to localhost on the VM matters.
Answer:
To do the opposite, I would use SSH local port forwarding with the -L option. In this case, the service is running on localhost:5432 on the VM, and I want to reach it from my laptop without making it public.
The command is:
ssh -L 5432:localhost:5432 macc@136.112.29.231
- Where
maccis my user for my GCP VM and136.112.29.231is the external IP exposed for my GCP VM. - This opens a port on the remote machine (5432), that my laptop can directly point to through the same port number.
After running that command, I could connect from my laptop to:
localhost:5432
My laptop will now connect as if the service was local, even though it is actually running on the VM.
Binding the service to localhost on the VM is important because it means the service is only listening for connections from the VM itself, not from the outside network. That makes it safer, since other VMs or external machines cannot connect to it directly (it does not have an external IP). The only way to reach it from my laptop is through the SSH tunnel, so it stays private without needing to expose port 5432 publicly.
Also, instead of using the full SSH command every time, this can also be configured in ~/.ssh/config using the LocalForward option, which allows setting up the tunnel automatically when connecting to the host.
4 The effect of buffer size on I/O
Write a C/C++ program to implement the cp command. This command is invoked as
cp <src> <dest>
It copies the contents of the binary file at src to dest. If dest already exists, then you should overwrite it, but if it does not exist, then you should create it with the permission rw-------. Do not use stdio or iostream (C++). Use raw system calls only—such as open, read, write to perform the copy. Plot the (usr + sys) times that it takes to copy an ≈100MB file if you perform reads and writes in granularity of 1, 2, 4, 8, 16, 32, . . . 4K bytes. What do you conclude from the results?
1. What the real cp command does
When you run:
cp src dest
the OS basically does this:
- open the source file for reading
- open or create the destination file for writing
- repeatedly:
- read a chunk of bytes from the source
- write that chunk to the destination
- stop when
read()says “end of file” - close both files
2. What a file descriptor is
A file descriptor is just a small integer the kernel gives you when you open a file.
For example:
int fd = open("file.txt", O_RDONLY);
- If it works,
fdmight be 3, 4, etc.
Then you use that number with read(), write(), and close().
3. The system calls we need
open()
Used to open a file.
Source file
For the source, you want read-only:
int src_fd = open(src, O_RDONLY);
Destination file
For the destination, you want:
- open for writing
- create it if it does not exist
- overwrite it if it already exists
int dst_fd = open(dest, O_WRONLY | O_CREAT | O_TRUNC, S_IRUSR | S_IWUSR);
- What those flags mean
O_WRONLY= open for writingO_CREAT= create if missingO_TRUNC= if it already exists, erase old contents first
- What
S_IRUSR | S_IWUSRmeans- This is permission
rw-------S_IRUSR= owner can read
S_IWUSR= owner can write
- This is permission
read()
ssize_t bytes_read = read(src_fd, buffer, buffer_size);
- It tries to read up to
buffer_sizebytes intobuffer.
Possible results:
> 0→ number of bytes actually read0→ end of file-1→ error
write()
ssize_t bytes_written = write(dst_fd, buffer, bytes_read);
- Important detail:
write()might write less than requested. - So even if you ask it to write 1024 bytes, it might only write, say, 700. Then you must write the rest yourself.
- That is why a loop around
write()is important.
close()
close(src_fd);
close(dst_fd);
- Always close your file descriptors at the end.
4. Implementation
#include <fcntl.h>      // open
#include <unistd.h>     // read, write, close
#include <sys/stat.h>   // permission flags
#include <cstring>
#include <cstdlib>

int main(int argc, char* argv[]) {
    // Check number of parameters is correct
    if (argc != 4) {
        // wrong number of parameters given
        const char* msg = "Usage: ./my_cp <src> <dst> <buffer_size>\n";
        write(STDERR_FILENO, msg, strlen(msg));
        return 1;
    }

    // Check parameters themselves
    const char* src = argv[1];
    const char* dest = argv[2];
    size_t buffsize = static_cast<size_t>(atoi(argv[3]));

    if (buffsize == 0) {
        const char* msg = "Buffer size must be > 0\n";
        write(STDERR_FILENO, msg, strlen(msg));
        return 1;
    }

    // Open the source file for reading
    int source_fd = open(src, O_RDONLY);
    if (source_fd < 0) {
        const char* msg = "Failed to open source\n";
        write(STDERR_FILENO, msg, strlen(msg));
        return 1;
    }

    // Open the destination file for writing|create|truncate|rw-------
    int dest_fd = open(dest, O_WRONLY | O_CREAT | O_TRUNC, S_IRUSR | S_IWUSR);
    if (dest_fd < 0) {
        const char* msg = "Failed to open destination\n";
        write(STDERR_FILENO, msg, strlen(msg));
        close(source_fd);
        return 1;
    }

    char* buff = new char[buffsize];

    while (true) {
        // Read the source file into a buffer
        ssize_t n = read(source_fd, buff, buffsize);

        // Error reading (-1)
        if (n < 0) {
            const char* msg = "Read error\n";
            write(STDERR_FILENO, msg, strlen(msg));
            delete[] buff;
            close(source_fd);
            close(dest_fd);
            return 1;
        }

        // Reached EOF
        if (n == 0) break;

        ssize_t offset = 0;
        while (offset < n) {
            // Write buffer to the destination file
            ssize_t w = write(dest_fd, buff + offset, n - offset);

            // Error writing (-1)
            if (w < 0) {
                const char* msg = "Write error\n";
                write(STDERR_FILENO, msg, strlen(msg));
                delete[] buff;
                close(source_fd);
                close(dest_fd);
                return 1;
            }

            offset += w;
        }
    }

    // Clean after successful copy
    delete[] buff;
    close(source_fd);
    close(dest_fd);
    return 0;
}
Compile:
g++ -std=c++17 -Wall -Wextra -O2 my_cp.cpp -o my_cp
Run it:
./mycp source.bin copied.bin 1024
That means:
- copy source.bin
- into copied.bin
- using a buffer of 1024 bytes
5. Why buffer size matters
Every time you call read() and write(), you are making a system call.
System calls are more expensive than normal function calls because the CPU has to switch between user mode and kernel mode.
So:
- small buffer → many read/write calls → more overhead
- larger buffer → fewer read/write calls → less overhead
We need to test the following buffer sizes (1, 2, 4, 8, 16, 32, … 4K bytes):
1
2
4
8
16
32
64
128
256
512
1024
2048
4096
Create a 100MB file:
On Linux, a common way is:
dd if=/dev/urandom of=testfile.bin bs=1M count=100
- That gives you a 100MB binary file.
If you want a faster file to generate:
dd if=/dev/zero of=testfile.bin bs=1M count=100
6. How to measure (usr + sys) time
Use the shell time command.
Example:
time ./my_cp testfile.bin out.bin 1
It will print something like:
real    0m4.231s
user    0m0.010s
sys     0m2.924s
Your homework wants user + system time, so you add:
usr + sys = 0.010 + 2.924 = 2.934 seconds
- You should do that for every buffer size.
Sometimes shell time formatting varies. A more convenient version is:
/usr/bin/time -f "%U %S" ./mycp testfile.bin out.bin 1024
This prints:
0.01 0.24
Important: remove the output file each time
Example repeated testing:
./my_cp testfile.bin out.bin 1024
./my_cp testfile.bin out.bin 2048
Automated testing
We can use a shell loop:
for bs in 1 2 4 8 16 32 64 128 256 512 1024 2048 4096
do
    echo "Buffer size: $bs"
    time ./my_cp testfile.bin out.bin $bs
done
Output:
> for bs in 1 2 4 8 16 32 64 128 256 512 1024 2048 4096
do
    echo "Buffer size: $bs"
    time ./my_cp testfile.bin out.bin $bs
done
Buffer size: 1
./my_cp testfile.bin out.bin $bs  11.53s user 196.79s system 98% cpu 3:31.23 total
Buffer size: 2
./my_cp testfile.bin out.bin $bs  5.61s user 98.22s system 98% cpu 1:45.20 total
Buffer size: 4
./my_cp testfile.bin out.bin $bs  2.78s user 47.58s system 99% cpu 50.744 total
Buffer size: 8
./my_cp testfile.bin out.bin $bs  1.38s user 23.16s system 99% cpu 24.667 total
Buffer size: 16
./my_cp testfile.bin out.bin $bs  0.69s user 11.82s system 99% cpu 12.593 total
Buffer size: 32
./my_cp testfile.bin out.bin $bs  0.35s user 5.73s system 99% cpu 6.103 total
Buffer size: 64
./my_cp testfile.bin out.bin $bs  0.18s user 2.89s system 99% cpu 3.081 total
Buffer size: 128
./my_cp testfile.bin out.bin $bs  0.09s user 1.46s system 98% cpu 1.565 total
Buffer size: 256
./my_cp testfile.bin out.bin $bs  0.04s user 0.74s system 99% cpu 0.787 total
Buffer size: 512
./my_cp testfile.bin out.bin $bs  0.02s user 0.37s system 98% cpu 0.402 total
Buffer size: 1024
./my_cp testfile.bin out.bin $bs  0.01s user 0.19s system 97% cpu 0.212 total
Buffer size: 2048
./my_cp testfile.bin out.bin $bs  0.01s user 0.10s system 97% cpu 0.114 total
Buffer size: 4096
./my_cp testfile.bin out.bin $bs  0.00s user 0.06s system 97% cpu 0.065 total
Results
| Buffer size (bytes) | User + System (s) |
|---|---|
| 1 | 208.32 |
| 2 | 103.83 |
| 4 | 50.36 |
| 8 | 24.54 |
| 16 | 12.51 |
| 32 | 6.08 |
| 64 | 3.07 |
| 128 | 1.55 |
| 256 | 0.78 |
| 512 | 0.39 |
| 1024 | 0.20 |
| 2048 | 0.11 |
| 4096 | 0.06 |
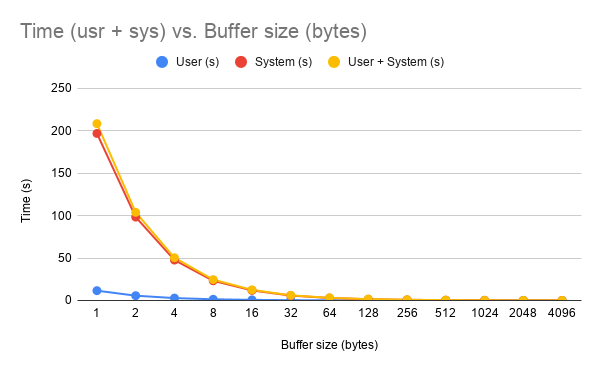
Conclusion:
As the buffer size increases, the (usr + sys) time drops very quickly. Very small buffers are extremely inefficient because the program has to make a huge number of read() and write() system calls. Once the buffer gets larger, the overhead of system calls becomes much smaller, so the copy runs much faster. By the time the buffer reaches a few KB, the improvement starts to level off.