11 - Concurrency and Threads
Class: CSCE-313
Notes:
Outline:
- What is concurrency?
- Macro illusion that multiple things are happening at the same time
- What is a thread?
- A useful abstraction for a program to program in a concurrent world
- Thread context switch
- Thread API
What is concurrency?
Concurrency is the execution of a set of multiple instruction
streams at the "same" time. This occurs when there are several
processes (or threads) executing in parallel.
Notes:
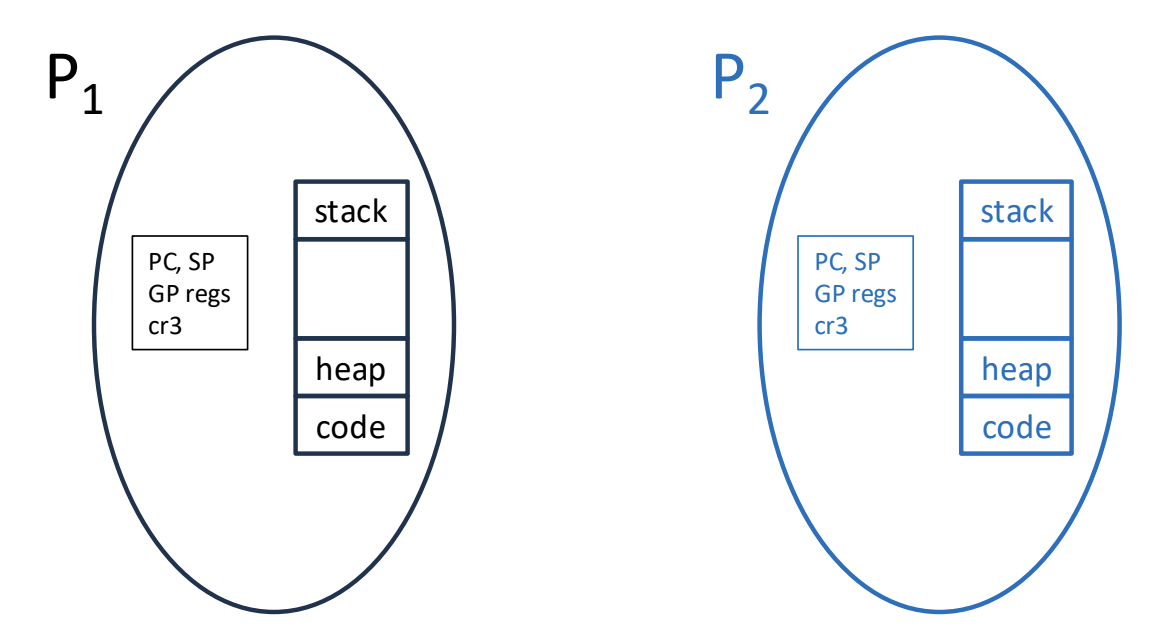
- Here we have two processes
- Concurrency is basically the macro view of P1 and P2 executing seemingly at the same time
- Concurrency is the macro-level illusion that multiple tasks are happening at the exact same time. On a single-core processor, the OS achieves this by rapidly context-switching between instruction streams so quickly that it looks simultaneous.
- In a multi-core processor you achieve parallelism (real concurrency) but for a single core it looks like everything is running concurrently
- Parallelism is true simultaneous execution, which can only happen if you have a multi-core processor where physical CPU cores are executing different instruction streams at the exact same microsecond.
What is a thread?
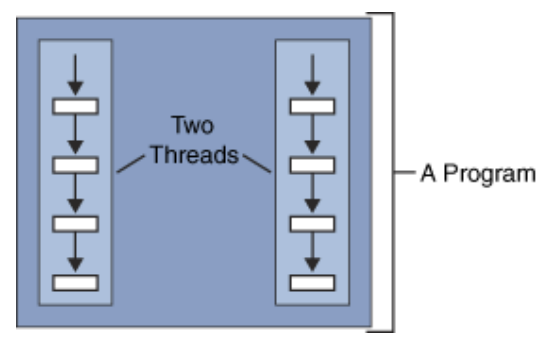
- A thread is a single sequential flow of control within a process.
- Provides a programmatic framework to organize code that exploits concurrency and parallelism.
- A UNIX process can be thought of as "executing" a single thread of control: each process is doing only one thing at a time.
- With multiple threads, a program can do more than one thing at a time within a single process; with each thread handling a separate task.
Notes:
- A thread is a single, sequential flow of control (a sequence of executing instructions) living inside a process.
- Traditionally, a UNIX process only has one thread (it can only do one thing at a time). By introducing multiple threads, you give your program a specific framework to exploit the hardware's concurrency/parallelism. It allows a single process to juggle multiple tasks at once.
Threads as a programmatic framework
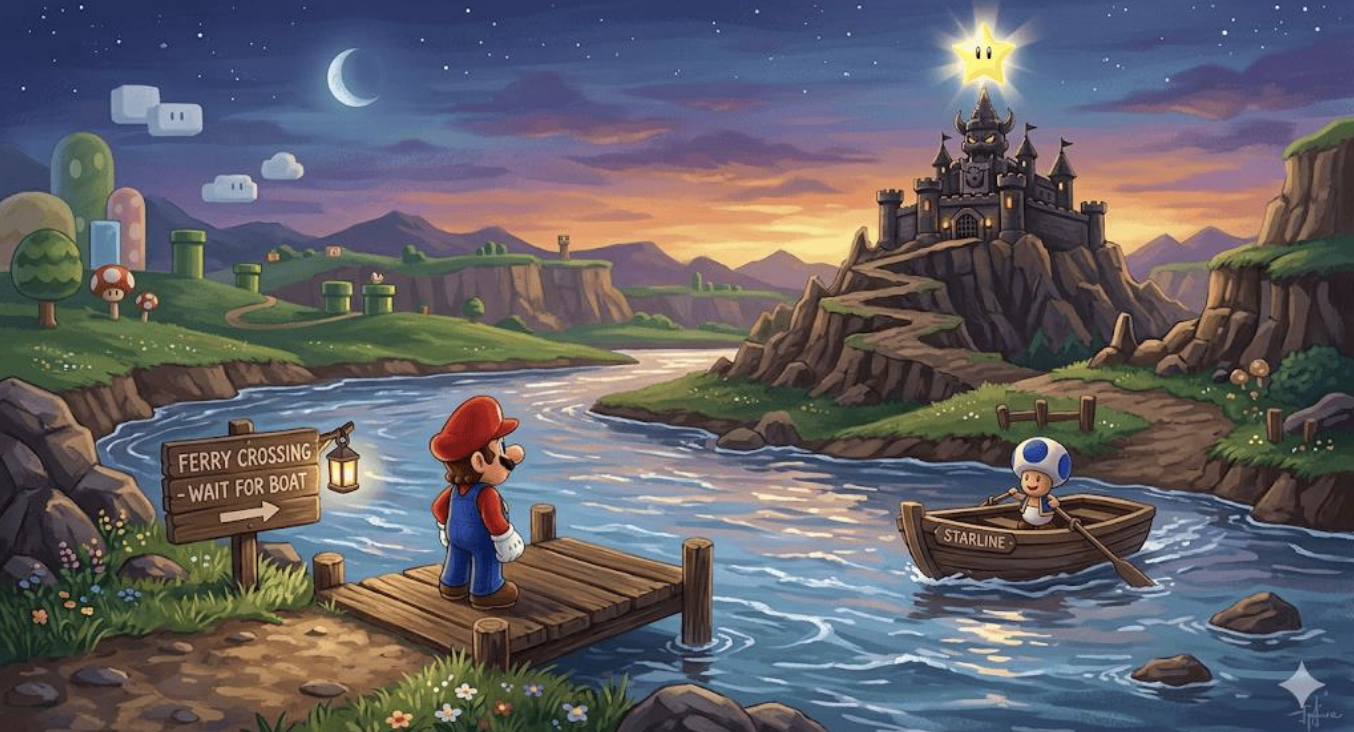
- In a single threaded world, Mario is blocked when reaching the river
- While he is blocked, he can't do any useful work, he has to wait for Toad to get him on the boat and bring him to the other side of the river.
- In a multi-threaded world, supposing you have a way to express that multiple things happen at the same time, Mario has a virtual Mario, and when one Mario is blocked, it can activate the other Mario and in that way proceed to the castle to get the magic boat
- The same happens when coming back
- This Mario is essentially hiding its latency by doing useful work!
- This is how you organize your computation around threads.
Notes:
- The Problem: In a single-threaded world, if your program needs to read a file from the slow hard drive, the entire program pauses (blocks) and does absolutely nothing until the disk finishes. Just like Mario arriving at a river and having to stand still while waiting for Toad's boat.
- The Solution: With multiple threads, you have "virtual Marios." When Thread A gets blocked waiting for the disk (or a network response), the OS instantly context-switches to Thread B, which can continue calculating data or rendering the screen.
- The Result: Threads allow you to hide the latency of execution. Instead of wasting CPU cycles while waiting for slow operations, you overlap that waiting time with actual, useful computation in another thread.
Multi-threaded process
Notes:
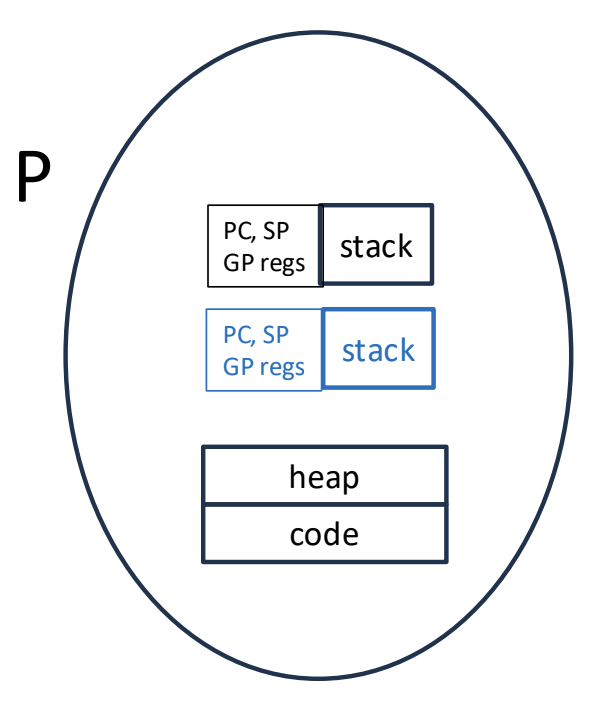
- User-Space vs. Kernel-Space Threads: In some threading models, threads are managed entirely in "user space" by a library and are invisible to the OS kernel. To the kernel, it just looks like one standard, single-threaded process.
- The Scheduling Implication: Because the kernel doesn't know these user-level threads exist, if one thread blocks (e.g., waits for I/O), the kernel will pause the entire process, unintentionally blocking all the other threads inside it. If the kernel does know about the multiple threads (kernel-level threads), it can intelligently schedule another thread from that same process to run while the first one is blocked.
- Work vs. Latency: Multi-threading doesn't magically decrease the total amount of CPU computation required for a task. Instead, its main goal is reducing latency (how long you have to wait for the result) by restructuring how that work overlaps.
Process vs. Thread
Each thread has its own:
- stack
- registers such as %rsp, %rip...
- sigmask
Threads share
- address space
- data
- code
- open files
- signal disposition
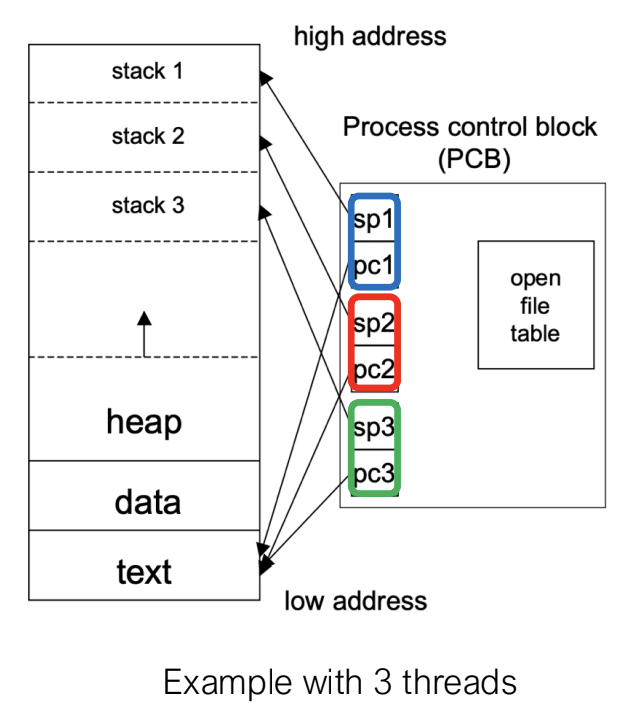
Notes:
- Each thread in a process has its own stack
- Each thread is invoking functions in its own data (data dependent)
- They also keep their own CPU context (registers)
sigmaskis per thread also
- But they share other things (heap, data, text, etc)
- Because a process is a container, they all share the same signal disposition (the same signal handlers and so on.)
Motivation for Threads
Basically two reasons:
- Parallelism to reduce time to completion of a given task
- True parallelism.
- Improve latency when a thread blocks on I/O
- 10 web requests each taking 100 ms .
- 1 thread takes
. - 10 threads take
. - Big change in latency.
- But perhaps the same CPU cost.
- Processes are expensive to create
- It takes time to switch between processes
- May suffer cache and TLB misses on context switch
- Communication between processes may need to be done through external structures such as files, pipes, etc
- Synchronization between processes may be cumbersome
Notes:
- Reason 1: Parallelism (Speed): If you have a multi-core processor, threads allow you to achieve true parallelism. You can divide a massive calculation among multiple threads, put each on a separate physical core, and reduce the total time to completion.
- Reason 2: Hiding Latency (Efficiency): Threads are incredibly powerful for overlapping I/O wait times.
- The Web Server Example: Imagine a server must make 10 database requests, each taking 100ms of waiting time. A single-threaded program must do these sequentially, taking 1000ms (1 full second). A 10-thread program can issue all 10 requests simultaneously. Because the waiting overlaps, the entire batch finishes in just 100ms.
Process Context Switch
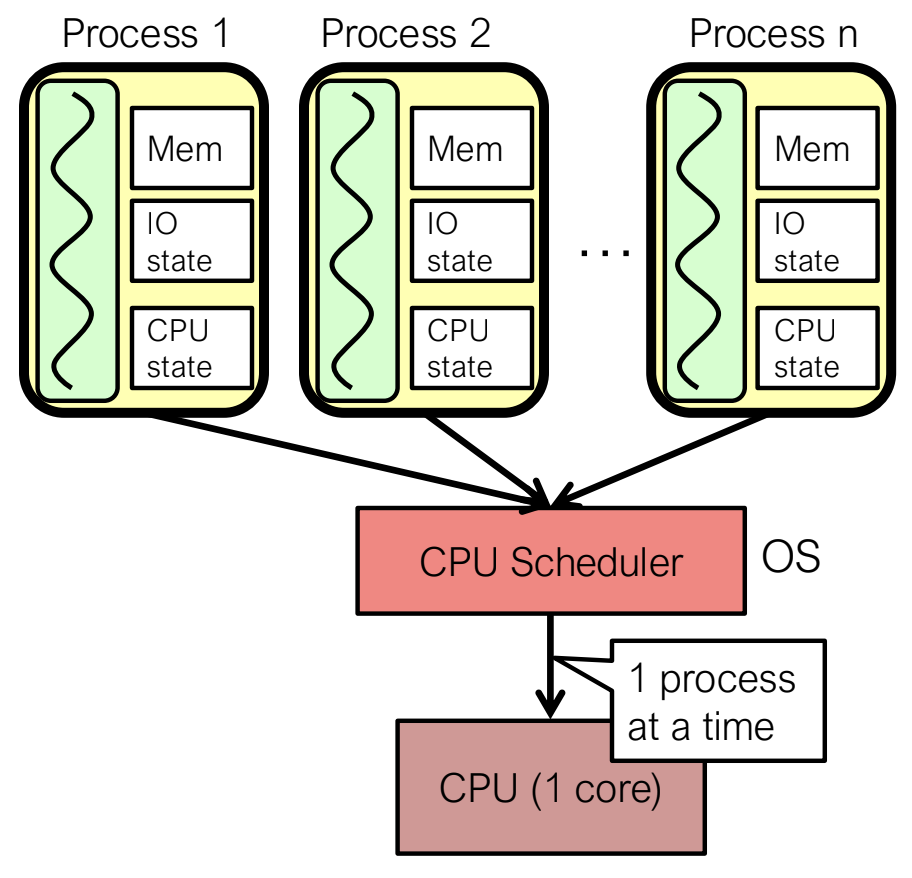
- Process switch overhead: high
- CPU state: low
- Memory/IO state: high
- Process creation: high
- Protection
- CPU: No
- Memory/IO: yes
- Sharing overhead: high (involves at least a context switch)
Notes:
- The Heavy Cost of Processes: A process context switch is fundamentally "expensive" (high overhead). While saving the raw CPU state (registers and Program Counter) is relatively fast, switching the Memory and I/O state is highly expensive.
- The Cache Penalty: Because each process is an independent container with its own virtual address space, a context switch forces the CPU to flush its TLB (Translation Lookaside Buffer) and caches.
- The Trade-off (Protection vs. Sharing): Processes provide strict protection for Memory and I/O—one process cannot accidentally overwrite another's memory. However, this strict isolation means sharing data is cumbersome and high-overhead, requiring complex Inter-Process Communication (IPC) mechanisms and forced context switches.
Thread Context Switch
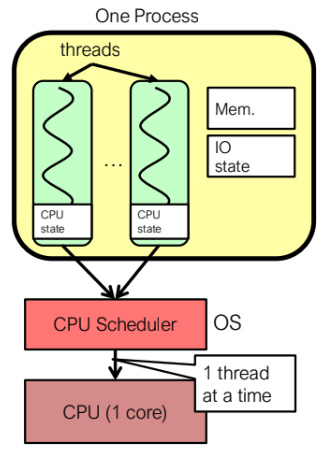
- Thread Switch overhead: low
- Only CPU state switched
- Thread creation: low
- Protection
- CPU: No
- Memory/IO: No
- Sharing overhead: low
- Low-overhead thread-switches
Notes:
- The Lightweight Alternative: A thread context switch is extremely lightweight (low overhead).
- Keeping the Cache Warm: Because threads within the same process share the exact same virtual address space, the OS only needs to switch the CPU state (registers and stack pointer). It does not need to switch the address space, so the CPU caches stay "warm" and everything one thread just loaded into the cache is instantly valid for the next thread.
- The Trade-off (Sharing vs. Protection): Data sharing is virtually free (low overhead) since threads naturally read and write to the same memory. However, this comes at the cost of absolutely zero Memory/I/O protection. A bug in one thread can easily corrupt the shared data for all other threads in the process.
- The Golden Rule: Because thread switches are so fast, the moment a thread blocks waiting for I/O, the system should immediately context switch to another thread so you don't waste useful CPU time.
Thread-based applications
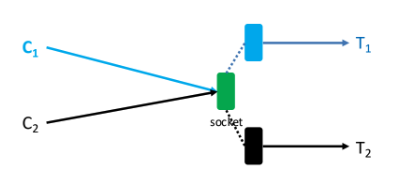
Manager/worker: a single manager thread assigns work to other threads, the workers. The manager handles all input and assigns tasks to worker threads.
- E.g., web server handling each request in a thread
Pipeline: A task is split into sub-operations, which are handled in series, but concurrently, by a different thread. For e.g., an automobile assembly line.
Notes:
- One manager and workers receiving work
- Pipeline:
- Each thread does some part of the pipeline
- Somebody fixing engine, somebody doing something else, etc.
Threaded web server
Notes:
- A threaded web server is the classic example of the Manager/Worker pattern.
- The main manager thread listens for incoming HTTP requests over the network. Once a request arrives, the manager's only job is to frame/package the request and assign it to an idle worker thread. This allows the manager to immediately go back to listening for new connections, preventing the server from freezing up under heavy traffic.
Thread Execution
Creating a thread is like calling a function directly, with a slight difference shown below:
- A regular function call is blocking, i.e., the caller waits for the callee.
- A thread call is non-blocking. So, this is like
fork(), we create the thread, call the function inside, but do not wait.
Notes:
- Synchronous vs. Asynchronous: When you make a standard, synchronous function call, the execution is blocking; your program pauses and waits for the function to finish and return a result. However, creating a thread is non-blocking.
- The "Fork-like" Behavior: You provide the threading API with a specific function to execute, the OS creates a new thread to run that function, and control returns to your main program immediately. Your main program does not wait for the thread to finish; it simply moves on to the next line of code, running concurrently with the newly created thread.
Problem with shared addresses-I
- If threads work on separate data, then scheduling may not matter.
- Initially
- What are the possible values of
? - x=13
- x=5
- x=3
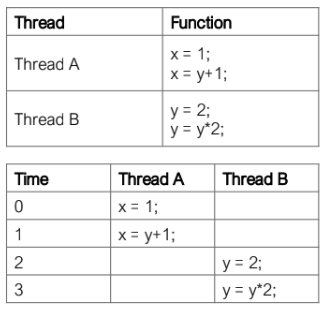
Notes:
- The used of threads has been debated hardly for decades in the computer science community
- One single threaded asynchronous loop vs multi-thread
- The Blessing and the Curse of Shared Memory: Because all threads logically contained within a process share the exact same virtual address space, they can seamlessly read from and write to the same shared memory addresses.
- The Threat of Arbitrary Interleaving: The exact order in which threads execute is determined by the OS scheduler, and its decisions are completely unpredictable. The CPU can context-switch between Thread A and Thread B at any arbitrary microsecond.
- Non-Determinism: Because of this unpredictable interleaving, if threads are mutating shared data without coordination, the final computed value becomes entirely non-deterministic. As a programmer, you must assume that any possible interleaving of instructions can and will happen in the wild.
The race condition problem
Race condition: the output of a concurrent program depends on the order of operations between threads.
We cannot make any assumption about the relative speed of threads
Non-determinism is omnipresent:
- Scheduler's decision depends on many factors
Notes:
- What is a Race Condition? A race condition occurs when the final output of a concurrent program changes depending on the unpredictable scheduling order (relative speed) of its threads. If multiple threads touch the exact same variable, and at least one of them is modifying (writing to) it, you have a recipe for disaster.
- The join() Trap: To prevent these disasters, you might be tempted to force synchronization using
join(). Thejoin()command acts exactly likewait()does for processes—it blocks the caller until the specific thread finishes executing. However, if you rely onjoin()to prevent threads from overlapping, you are effectively running them sequentially. This completely negates the performance benefits of multi-threading because you are blocking yourself instead of doing useful concurrent work.
Rate condition in Assembly
- Compiler generated assembly based on the instruction set.
- Thread A: x = x+1
- Thread B: x = x+1
- Initially
- The value of
can be 1 or 2 depending on the order of execution.
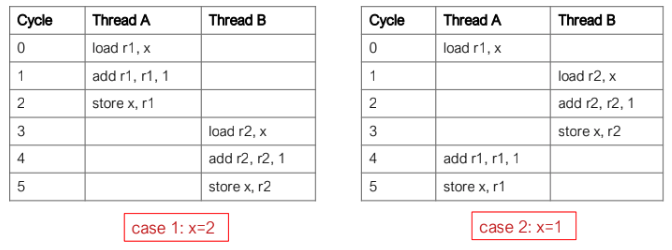
Notes:
- When you look at the actual execution in assembly, you could context switch anywhere
- Each one of these instructions is basically compiled to multiple statements, and now you have even less control of what is happening.
- Note that when a signal happens either an operation didn't start or finished completely, this is the definition of atomicity. There is a unit of consistency
- As a programmer that notion of consistency has to come from you, it is implemented by you by doing techniques like blocking.
Race condition may happen because of instruction reordering
Most architectures support this feature:
- Pipelined processors cannot achieve peek performance without it.
- The idea is simple: compilers may reorder "unrelated" instructions like the following:
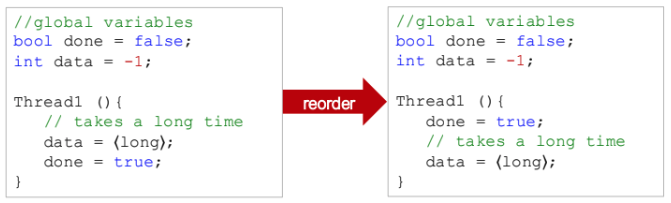
Notes:
- When you compile the first program you have:
- Data assigned to something that takes a long time to finish
- What the compiler does is that it sets done to true before it assigns data
- The assumption is violated, you cannot guarantee anything.
- But this is a legal optimization in a compiler, if you do not do reordering then you cannot optimize a lot.
Out-of-Order Execution causing Race Condition
- The problem arises when there is an inter-thread dependency
- Because of thread 2's wait, the 2 lines in Thread1() are no longer independent i.e., ordering is important
- However, the compiler has no way to tell that.

Notes:
- The Compiler Reordering Threat: Compilers are designed to optimize code. If a compiler sees two lines of code in a single thread that don't directly depend on each other (e.g., assigning a value to
data, and then setting a boolean flagdone = true), it might reorder them to make the CPU run faster. - Breaking Inter-Thread Dependencies: The problem is that the compiler has no idea that another thread might be relying on that specific order. If Thread 2 is spinning in a
waitloop looking fordone == truebefore it readsdata, the compiler's reordering will cause Thread 2 to read garbage/uninitialized data. - The Solution: Serialization & Critical Sections: To solve both unpredictable CPU interleaving and dangerous compiler reordering, you must introduce serialization (forcing things to happen sequentially rather than concurrently). You do this by defining Critical Sections (the "red blocks").
- The Rule of Mutual Exclusion: The fundamental rule of a critical section is that only one thread can be inside it at any given time. Thread A can go first, or Thread B can go first, but they can never execute that block of code simultaneously.
- Atomicity & Visibility: While a thread is inside a critical section, its intermediate changes are isolated. The moment the thread exits the critical section, all of its changes become magically and atomically visible to the next thread that enters.
- The Programmer's Burden: The compiler and the OS cannot guess where your shared variables are or what needs protecting. It is entirely the programmer's responsibility to identify these interfering pieces of code and wrap them in protections.
- The Tools: We achieve this protection by using synchronization primitives—specifically Locks or Mutexes (Mutual Exclusion objects).
pthread (POSIX thread) creation
With pthreads, when a program runs, it also starts out as a single process with a single thread of control.
The pthread_create() function starts a new thread in the calling process.
#include <pthread.h>
int pthread_create(pthread_t *tid, const pthread_attr_t *attr,
    void *(*func) (void *), void *arg);
tid: uniquely identifies a thread within a process and is returned by the functionattr: sets attributes such as priority & initial stack size. Can be NULL for defaultsfunc: function to call to start the thread. accepts a (void *) argument, returns (void *)arg: the argument to func
pthread_create returns 0 if successful, a positive error code if not.
C++ Thread API
#include <iostream>
#include <thread>
#include <unistd.h>
using namespace std;

void foo() {
    sleep(3);
    cout << "foo done" << endl;
}
void bar(int x) {
    sleep(1);
    cout << "bar done" << endl;
}

int main() {
    thread foothrd(foo); // calls foo() in a thread
    thread barthrd(bar, 77); // calls bar(x) in a thread
    cout << "main, foo and bar would now execute concurrently..." << endl;

    foothrd.join(); // pauses until foo finishes
    barthrd.join(); // pauses until bar finishes
    cout << "foo and bar completed." << endl;
    return 0;
}
- When the thread returns from
bar, the thread basically finishes, and waits - Threads competing from CPU
- One happens to run first
Output:
maon, foo, bar, fib execute concurrently ...
bar: received 77
foo: done
foo, bar, fib completed
- None is guaranteed to run first
Race Condition Demonstration
- Start two (or more) threads that increment a shared variable.
- Use a pointer to the data so that the threads share it.
- Use a large number of iteractions to ensure adequate overlap.
- Notice that the output is different every time.
#include <iostream>
#include <thread>
#include <unistd.h>
using namespace std;

void func(int *p, int x) {
    // increment *p x times
    for (int i = 0; i < x; i++)
    *p = *p + 1;
}

int main(int ac, char **av) {
    int data = 0;
    int times = atoi(av[1]);
    // start 2 threads to increment
    thread t1(func, &data, times);
    thread t2(func, &data, times);
    t1.join();
    t2.join();
    cout << "data=" << data << endl;
    return 0;
}
- We want to see two threads
- One incrementing something 100 times, and the other also incrementing it 100 times, will it increment 200 times?
root@ubuntu-csce313:~\# g++ race-condition.cc root@ubuntu-csce313:~\# ./a.out 100000 data=200000
root@ubuntu-csce313:~\# ./a.out 1000000 data=2000000
root@ubuntu-csce313:~\# ./a.out 10000000 data=10938339
root@ubuntu-csce313:~\# ./a.out 10000000 data=14035068
root@ubuntu-csce313:~\# ./a.out 10000000 data=17764839
root@ubuntu-csce313:~\# ./a.out 10000000 data=16256394
root@ubuntu-csce313:~\# ./a.out 10000000 data=14049964
- The reason for this is that writes by one are overwriting the writes for the other
- Imagine a situation where you have 2 threads that are executing, they both read the same variable, they both individually increment it, and they both them write back
- Both are reading, computing, and writing
- We want one of them to happen after the other
- By failing to serialize in this example you will have writes for one being overwritten by the other
- What does
join()do?- It blocks until a thread finishes.
- If we didn't have these, the thread will just terminate and call
exti()on our process.
Thread-safe functions
A function is said to be thread-safe if it can safely be invoked by multiple threads at the same time; put conversely, if a function is not thread-safe, then we can't call it from one thread while it is being executed in another thread.
[Kerrisk 31.1]
Not all functions can be called from threads
- Many functions use global/static variables
- New versions of UNIX have thread-safe replacements like
strtok_r()
Safe functions
ctime_r(),gmtime_r(),localtime_r(),rand_r(),strtok_r()
Unsafe functions
ctime(),gmtime(),localtime(),rand(),strtok(),gethostxxx()