14 - Into to Networking
Class: CSCE-313
Notes:
3rd midterm on Friday 4/24 or Mon 4/27
Try to work out problems under Weekly-HW
- Doing this will help you understand the material better
What is a network?
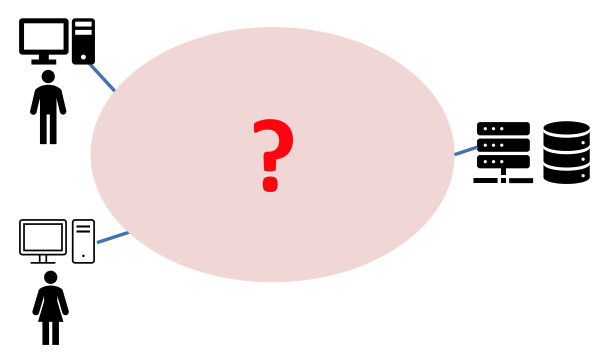
Notes:
- Every device that you will probably ever used is at the edge of the network, you are always connecting at the edge
- You are connecting from something called an Access Point, that is then connected to the network
- If you connect a Cat6 cable to you PC, you are connecting from the edge
- Something inside is able to make a connection from you from whenever you are in the entire planet
- We are just interested in the API at the end devices, we are interested on that software that enables us to connect to the internet
The network does the routing
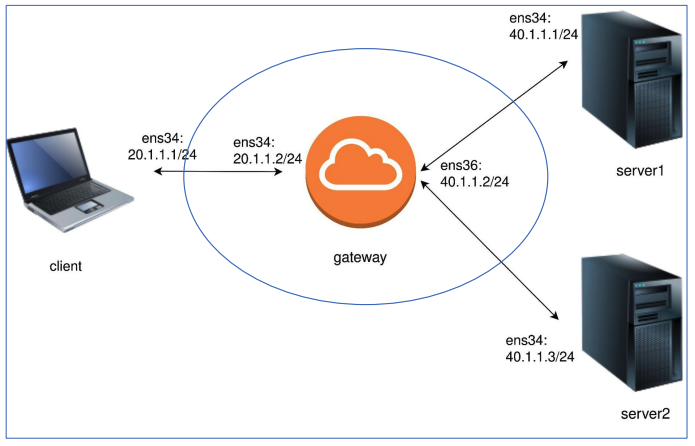
Notes:
- The only thing you know is how to reach your default gateway (the first hope device in the network that knows a lot more about the network than you do)
- Lets say you want to get to google.com, you create a packet and just send it to your gateway, it will receive it, parse it and route to wherever you are directing to.
- For every packet you have to read it from your NIC into your memory, parse it...
- The gateway decides on which direction to go, it does some hash or search in order to figure out on which direction to send it
The Internet: a "nuts and bolts" view
Billions of connected computing devices:
- hosts = end systems
- running network apps at Internet's "edge"
Packet switches: forward packets (chunks of data)
- routers, switches
Communication links
- fiber, copper, radio, satellite
- transmission rate: bandwidth
Networks
- collection of devices, routers, links: managed by an organization
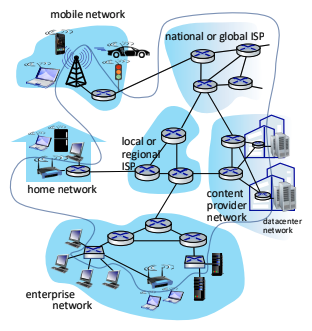
Notes:
- Every blue region is a network
- You may be in your home and all the devices in your home may be connected to an access point
- Traffic from your phone is going from devices to your router to your local ISP (optimum, etc.) - they server either your local area or some region
- There is this notion of an Autonomous system in the internet: it is an independently managed network
- They own certain set of pre-fixes and advertise them, when you want to reach a destination, you basically route it to the autonomous system
- It is actually pretty fragmented for a lot of reasons
- Billions of connected devices
- Switches route at layer 2
- Routers route at layer 3
"Fun" Internet-connected devices
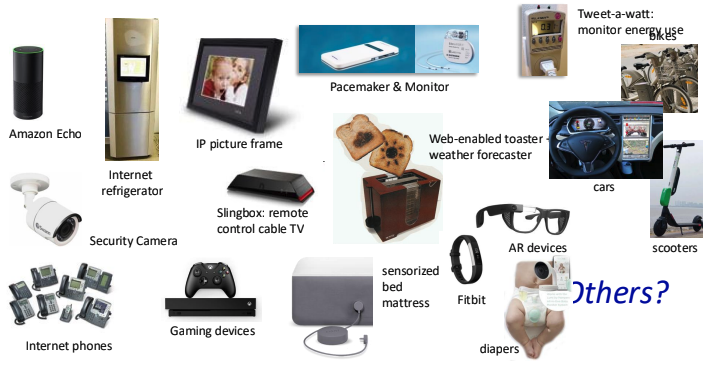
Notes:
- They all want to be first-class citizens at the edge
- They are truly first-class entities in the network, but unfortunately they cannot always can be due to addressing limitations
The functionality of "networking"
Networking does much for applications.
- Name communication endpoints
- Make and break connections
- Find a path through the network
- Transfer information reliably
- Transfer arbitrary length information
- Send as fast as the network allows
- Share bandwidth among users
- Secure information in transit
- Let new hosts be added
Notes:
- One of the functionalities of the network API is the ability to name devices at the edge
- The way you communicate with someone is that you construct a packet, you put your destinations 32-bit number, you put your own 32-bit number as the source and you forward it to the network so that it gets routed to your destination.
- The cloud in the middle does the route for you, you just need to name an endpoint
- Modern networking is packet switched rather than connection-based
- Split conversation into little discrete packets, each of these packets has a destination and source IP
- We are individually routing each of these packets
- every individual packet is routed independently
- they do not necessarily need to take the same path on the network
- These packets can arrive out of order
- The third packet comes first, then the first, then the second for example
- The endpoint needs to do something in order to assemble the plackets in order
- It also can happen that a packet gets duplicated
- Every node in the middle will receive the packet, search for its destination and forward to the next node in the network.
- We need to have some convoluted logic in order to figure out reassembly of packages and re-fragmenting, removing duplicates
- But all of this is being done for you and its done at the edge!
- There is a notion of connection
- The sender and the receiver sort of agree that they are going to exchange messages, but before starting to send messages they need to set up a connection
- Is not like once you reach the end of some counter you have to break the connection
- The throughput in the network can suddenly change if network gets congested
- The endpoints can figure this out and slow down the transmission rate
- How this happens is also something that your networking stack is able to figure out
- There are other signals to figure out that something bad is happening in the network
Rewritten notes:
- Endpoint Naming: A core function of the network API is giving communication endpoints a name, specifically using 32-bit IP addresses. To communicate, you just construct a packet with your source IP and the destination IP, and the network "cloud" handles the physical routing for you.
- Packet-Switched, Not Connection-Based: The modern internet fundamentally operates via packet switching. A long conversation or file is split into small, discrete chunks (packets), each stamped with the source and destination IPs.
- The Chaos of the Cloud: Every individual packet is routed completely independently. This means packets belonging to the same file might take entirely different physical paths across the world. Consequently, packets can arrive out of order, get delayed, or even get duplicated by routers along the way.
- Smart Edge, Dumb Network: The network fabric itself only worries about moving packets one hop at a time. All the complex logic—like reassembling out-of-order packets, dropping duplicates, handling dropped packets, and managing connection state—is done entirely by the software at the edge of the network (your computer's networking stack).
- Dynamic Throughput: Endpoints can sense if the network is getting congested (e.g., packets are taking too long or dropping) and will automatically slow down their transmission rates to prevent overwhelming the network.
Routing
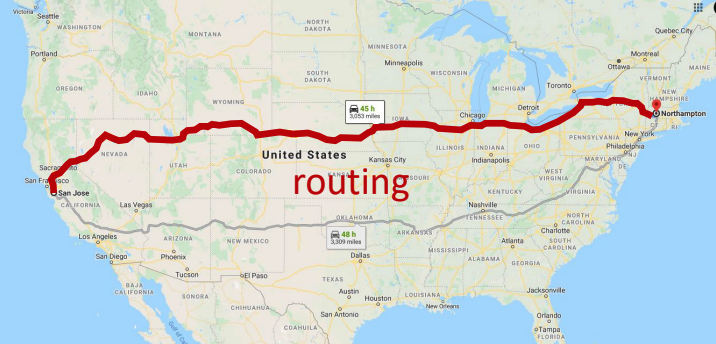
Packet forwarding
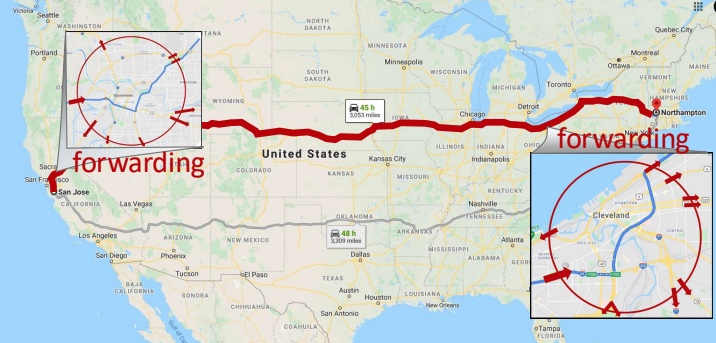
Notes:
- The Problem with Exact Addresses: If every router on the internet had to memorize the exact location of every single device (like knowing the exact street address of a house in Northampton from San Jose), routing tables would be impossibly large.
- Prefix Coalescing (Compression): To solve this, the internet routes based on prefixes. Instead of routing to a specific device, a distant router routes the packet to a massive geographic region or ISP. As the packet gets closer to the destination, the routers look at smaller and smaller prefixes (getting more specific) until it reaches the local network that actually owns the final address.
- The Router's Job: When a packet hits a router, the router looks at the destination IP and essentially makes one simple decision: "Out of all my connected physical interfaces (cables), which one should I send this packet down?". It uses a table to match the destination to a specific vector (direction/interface) and distance.
Examples:
┌──(macc㉿kaliLab)-[~]
└─$ ifconfig -a
eth0: flags=4163<UP,BROADCAST,RUNNING,MULTICAST>  mtu 1500
        inet 192.168.64.2  netmask 255.255.255.0  broadcast 192.168.64.255
        inet6 fd15:7568:1b93:9ef1:49a9:ac71:34f7:cb32  prefixlen 64  scopeid 0x0<global>
        inet6 fe80::60cf:81ff:fe55:308d  prefixlen 64  scopeid 0x20<link>
        inet6 fd15:7568:1b93:9ef1:60cf:81ff:fe55:308d  prefixlen 64  scopeid 0x0<global>
        ether 62:cf:81:55:30:8d  txqueuelen 1000  (Ethernet)
        RX packets 129735  bytes 97878313 (93.3 MiB)
        RX errors 0  dropped 0  overruns 0  frame 0
        TX packets 111498  bytes 19126431 (18.2 MiB)
        TX errors 0  dropped 0 overruns 0  carrier 0  collisions 0

lo: flags=73<UP,LOOPBACK,RUNNING>  mtu 65536
        inet 127.0.0.1  netmask 255.0.0.0
        inet6 ::1  prefixlen 128  scopeid 0x10<host>
        loop  txqueuelen 1000  (Local Loopback)
        RX packets 3450  bytes 13001871 (12.3 MiB)
        RX errors 0  dropped 0  overruns 0  frame 0
        TX packets 3450  bytes 13001871 (12.3 MiB)
        TX errors 0  dropped 0 overruns 0  carrier 0  collisions 0

tun0: flags=4305<UP,POINTOPOINT,RUNNING,NOARP,MULTICAST>  mtu 1500
        inet 10.10.14.2  netmask 255.255.254.0  destination 10.10.14.2
        inet6 fe80::8af5:89d2:6df1:a2d0  prefixlen 64  scopeid 0x20<link>
        inet6 dead:beef:2::1000  prefixlen 64  scopeid 0x0<global>
        unspec 00-00-00-00-00-00-00-00-00-00-00-00-00-00-00-00  txqueuelen 500(UNSPEC)
        RX packets 0  bytes 0 (0.0 B)
        RX errors 0  dropped 0  overruns 0  frame 0
        TX packets 20  bytes 2821 (2.7 KiB)
        TX errors 0  dropped 0 overruns 0  carrier 0  collisions 0
- The IP address of my VM is
192.168.64.2
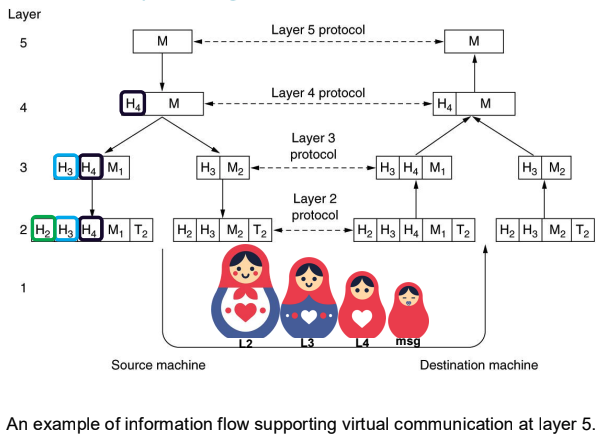
Protocol Layering
Notes:
- You are independent of what is at layer l - 1, l - 2 and so on.
- You can write you layer M by using functionality entirely at layer M - 1
- When you connect via
sshto your VM, every keystroke that you type can be converted to a packet that gets send to your VM- Your
sshclient is at layer 5 (application layer) - On layer 4 there will be a header encapsulating the your message with metadata of whatever the functionality of layer 4
- Layer 3 will do the same, at a header to the encapsulated message from layer 4 and encapsulate it again
- Layer 3 worries about what is going to happen if a frame is fragmented in the middle of the network, how it can be reconstructed, it also needs to put destination on source IP headers and so on.
- The layer 2 further adds its header and so on
- Your
- All of this layer is happening so that this guy uses its functionality of the previous layer and so on.
- Every character you type is potentially going through a different route that the endpoint has to later reassemble
Rewritten notes:
- Layer Independence: Each network layer M operates completely independently by utilizing the services of the layer directly beneath it (M−1).
- Encapsulation (The SSH Example): When you type a keystroke over SSH (Layer 5 - Application Layer), that data is passed down the stack. Layer 4 wraps it in a header with transport metadata. Layer 3 wraps it again with IP headers and handles complex logic like fragmentation (how to safely break apart and reconstruct packets if they are too large for the network). Layer 2 wraps it yet again with hardware-level headers.
- Reassembly: Because every packet might take a completely different physical route across the world, the receiving endpoint's networking stack must reverse this entire encapsulation process to reassemble the data in the correct order.
The Open System Interconnection (OSI) model
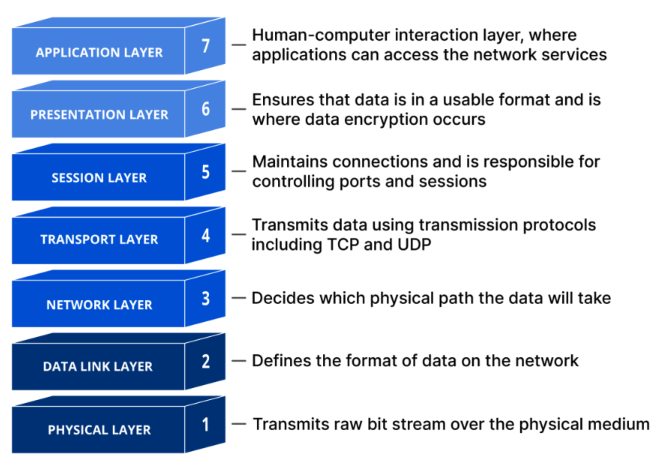
Notes:
- Theoretical vs. Practical: The OSI model is a theoretical 7-layer framework. However, in modern practice (the TCP/IP model), the top three OSI layers (Application, Presentation, and Session) are consolidated into a single Application layer. The application developer decides exactly how to handle these functionalities rather than relying on the OS.
- Sessions & Efficiency: Even though the "Session" layer is consolidated, the concept is crucial for secure protocols like HTTPS. Cryptography is computationally expensive. Instead of regenerating keys for every single packet, the application sets up the secure keys once and uses session resumption to quickly re-authenticate returning clients, saving massive amounts of processing power.
The TCP/IP Reference Model
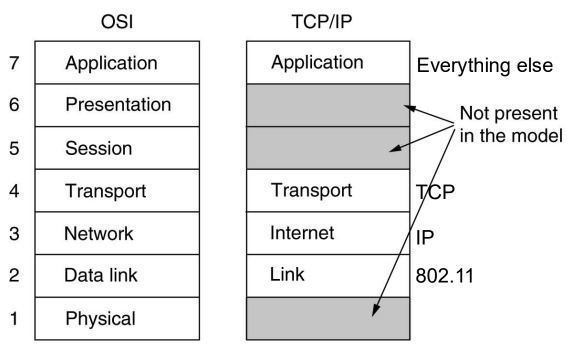
Notes:
- They do not have separate layers, you still need to do those, but it is the application that takes care of them
A client-server transaction
Most network applications are based on the client-server model.
- A server process and one or more client processes
- Server manages some resource
- Server provides service by manipulating resource for clients
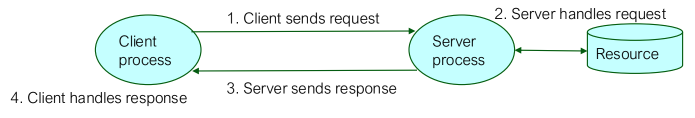
Clients and servers are processes running on hosts. They can be the same or
different hosts.
Notes:
- The Architecture: The vast majority of network applications use this model. A server process manages a specific resource, and one or more client processes request access to it.
- The Flow: The client sends a request across the network. The server intercepts it, parses the request, performs the necessary service (like fetching a file or executing a database query), and sends the response back. These processes can be running on opposite sides of the world, or locally on the exact same host machine.
What's a protocol?
A human protocol and a computer network protocol:
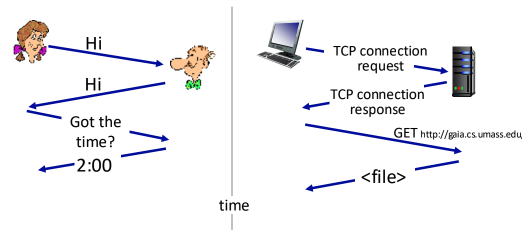
Protocols define the format, order of messages sent and received among network entities, and actions taken on message transmission, receipt
Notes
- The Rules of Communication: Just like human conversation requires mutual understanding (e.g., Alice asks a question, Bob replies), network entities need strict rules to communicate effectively without misinterpreting data.
- Definition: A protocol is the exact set of rules defining the format of messages, the order in which they must be exchanged, and the specific actions that must be taken when a message is transmitted or received.
Example of a client-server protocol:
curl
- Allows you to make HTTP request
- The server will read the request and serve the request
Example
┌──(macc㉿kaliLab)-[~]
└─$ curl -v https://www.google.com
- name resolves into addresses
- When you want to covert this name into an IP address, you will get a bunch of them
- Google will rotate these addresses, so if you make multiple requests it will go to different sites hosting the same, that is how load balancing works.
Here is the request that was send:
* Connected to www.google.com (142.251.151.119) port 443
* using HTTP/2
* [HTTP/2] [1] OPENED stream for https://www.google.com/
* [HTTP/2] [1] [:method: GET]
* [HTTP/2] [1] [:scheme: https]
* [HTTP/2] [1] [:authority: www.google.com]
* [HTTP/2] [1] [:path: /]
* [HTTP/2] [1] [user-agent: curl/8.15.0]
* [HTTP/2] [1] [accept: */*]
> GET / HTTP/2
> Host: www.google.com
> User-Agent: curl/8.15.0
> Accept: */*
>
* Request completely sent off
Response looks like:
< HTTP/2 200
< date: Mon, 06 Apr 2026 19:36:58 GMT
< expires: -1
< cache-control: private, max-age=0
< content-type: text/html; charset=ISO-8859-1
< content-security-policy-report-only:
...
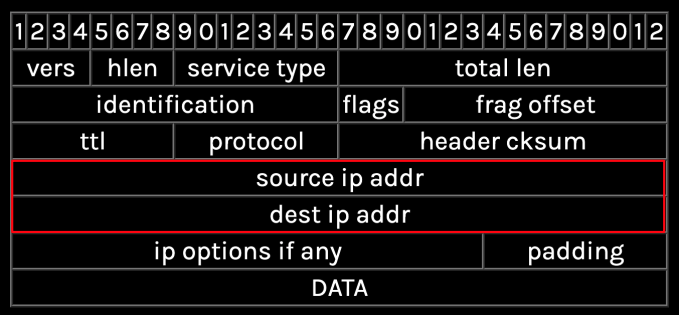
IP datagram
Notes:
- The Edge of the Cloud: Conceptually, you can think of the internet as one massive, homogenous cloud. As a programmer, your machine sits at the "edge" of this cloud. Your networking stack's job is simply to get data from your edge, through the fabric of the cloud, to another edge.
- Layer 3 (Network Layer): The Internet Protocol (IP) operates at Layer 3. Your stack discretizes your data into small packets to send into the network pipe, and the receiving stack at the other edge is responsible for fixing the sequence.
- The IP Header: Every individual IP packet contains a header with exactly two critical pieces of routing information: the 32-bit source IP address and the 32-bit destination IP address.
- Encapsulation: Because of protocol layering, the Layer 4 packet (e.g., the TCP packet) is entirely encapsulated inside the Layer 3 IP packet.
TCP header
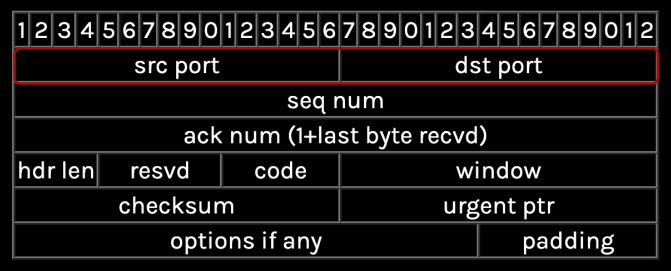
Notes:
- Routing to Services (Ports): While the IP header gets the packet to the correct machine, the TCP header (Layer 4) contains the destination port. This ensures the packet goes to the correct service running on that machine (e.g., port 80 for HTTP traffic, port 443 for secure HTTPS).
- Ensuring Reliability: The network cloud is chaotic, but TCP provides reliability. The TCP header uses forward sequence numbers and checksums to ensure that the receiving endpoint can correctly reassemble the out-of-order packets and detect data corruption
A programmer's view of the Internet
Hosts are mapped to a {set} of 32-bit IP addresses
- E.g. 128.194.255.88 (4 * 8 bits)
A set of identifiers called Internet domain names are mapped to the set of IP addresses for "human" convenience (Domain Name Server aka DNS)
- linux2.cs.tamu.edu is mapped to 128.194.166.90
- A process on one Internet host can communicate with a process on another Internet host over a connection
Notes:
- IP Addresses: From a programmer's perspective, internet hosts are mapped to a set of 32-bit IP addresses (like
128.194.255.88). Every network interface on your machine will be assigned its own IP address. - DNS (Domain Name Server): Because humans are bad at remembering 32-bit numbers, the internet uses DNS to translate human-readable domain names (like
linux2.cs.tamu.edu) into their mapped IP addresses. - The Ultimate Goal: The entire purpose of this architecture is to allow a process running on one internet host to establish a connection and communicate seamlessly with a process running on a completely different host.
Example:
> nslookup www.cs.tamu.edu
Server:         128.194.254.1
Address:        128.194.254.1#53

www.cs.tamu.edu canonical name = redirect.engr.tamu.edu.
redirect.engr.tamu.edu  canonical name = d3s3b8hbw2bor0.cloudfront.net.
Name:   d3s3b8hbw2bor0.cloudfront.net
Address: 3.169.221.28
Name:   d3s3b8hbw2bor0.cloudfront.net
Address: 3.169.221.94
Name:   d3s3b8hbw2bor0.cloudfront.net
Address: 3.169.221.95
Name:   d3s3b8hbw2bor0.cloudfront.net
Address: 3.169.221.22
- It corresponds to a machine somewhere sitting in TAMU
- As it turns out, it has 4 different IP addresses that you can reach out
> dig +short www.google.com
142.251.152.119
142.251.153.119
142.251.154.119
142.251.155.119
142.251.156.119
142.251.157.119
142.251.150.119
142.251.151.119
- When you reach to google.com in your browser you are picking one of these!
- Note if you do it again, the order of the entries would change, this is because of the load balancing made by google.
IP Addresses
32-bit IP addresses are stored in an IP address struct
- IP addresses are stored in memory in network byte order (big-endian byte order)
- Big-endian means the most significant byte first, for instance a short 0x5F2D will be stored as 5F 2D, i.e., in bytes
. - Little-endian means they are stored as:
bytes[0]=2D,bytes[1]=5F.
- Big-endian means the most significant byte first, for instance a short 0x5F2D will be stored as 5F 2D, i.e., in bytes
- Generally true for any integer tx in a packet header from one machine to another
/* Internet address structure */
struct in_addr {
    in_addr_t s_addr; /* network byte order (big-endian) */
};
Handy network byte-order conversion functions:
htonl: convertuint32_tfrom host to network byte orderhtons: convertuint16_tfrom host to network byte orderntohl: convertuint32_tfrom network to host byte orderntohs: convertuint16_tfrom network to host byte order
Notes:
- We will only look at IPv4 in this class
- The IPv4 Struct: In C network programming (focusing on IPv4), a 32-bit IP address is simply wrapped inside a structure called
struct in_addr. This structure acts as a distinct type to tell the compiler "this integer is an Internet Address." - The Endianness Problem: Different computer architectures store multi-byte integers in memory differently. For example, Mac and Intel processors are typically Little-Endian (least significant byte stored first), while other architectures might be Big-Endian. If a little-endian client sends an IP address or port number over the network as-is, a big-endian server will read the bytes backward and route data to the completely wrong place.
Byte order for shorts and ints
#include <stdio.h>
#include <arpa/inet.h>
int main() {
    uint32_t a = 0x01020304;
    char *p = (char *) &a;
    printf("%x %x %x %x\n", p[0], p[1], p[2], p[3]),
    a = htonl(a);
    printf("%x %x %x %x\n", p[0], p[1], p[2], p[3]);
    return 0;
}
Notes:
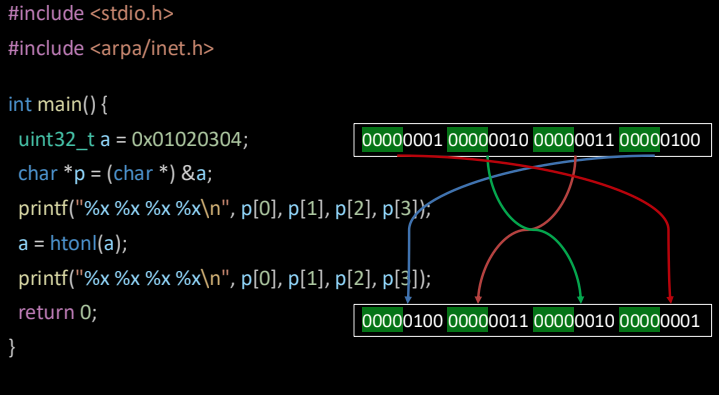
- This example illustrates endianness of network architecture
- Number is just a hex value (i.e. 0x01020304)
- If you are reading this number like that you are inherently assuming endianness, but different architectures do different things
- We have these two big forms:
- Little endian
- Big endian
- The Network Standard (Big-Endian): To solve this chaos, the internet standard dictates a universal Network Byte Order, which is strictly Big-Endian (most significant byte first).
- Conversion Functions: Before sending any integer (like an IP or a port) over the network, you must convert it from your machine's local format to the network format.
htonl()/htons(): Converts Host to Network. Use 'l' (long, 32-bit) for IP addresses, and 's' (short, 16-bit) for port numbers.ntohl()/ntohs(): Converts Network to Host. Used when receiving data.
- Code:
- You will do the assignment, then print the first 4 bytes
- A function called
htonlmeans: host to network long - Once we have turn
ato this "network long" we do this again
Result:
Host BO: 4 3 2 1
Network BO: 1 2 3 4
inet_ntop: 1.2.3.4.
- Note Mac is is little endian so the first sequence appears from the least significant byte to the most significant byte.
- The network does this differently, it is big endian.
- The receiver must know what is the byte order of the source ip address and the byte order of the destination ip address so it can decide the appropriate way to pack the bytes.
Dotted Decimal Notation
By convention, each byte in a 32-bit IP address is represented by its decimal value and separated by a period
- IP address 0x8002C2F2 = 128.2.194.242
Functions for converting between binary IP addresses and dotted decimal strings:
inet_pton: converts a dotted decimal string to an IP address in network byte orderinet_ntop: converts an IP address in network byte order to its corresponding dotted decimal string. See Section 16.3.2 of APUE.- "
" denotes network representation, " " denotes presentation representation. 0x8002C2F2 → "128.2.194.242"
Notes:
- Human Readability: Humans are bad at reading raw 32-bit hex values like
0x8002C2F2. By convention, we use "dotted decimal notation," which breaks the 32-bits into 4 individual bytes and writes each in decimal separated by periods (e.g.,128.2.194.242). - Presentation Translation: The C API provides utility functions to seamlessly convert between human-readable strings (Presentation) and 32-bit binary network data (Network):
inet_pton(): Converts presentation (string) to network (binary).inet_ntop(): Converts network (binary) to presentation (string).
Internet domain names
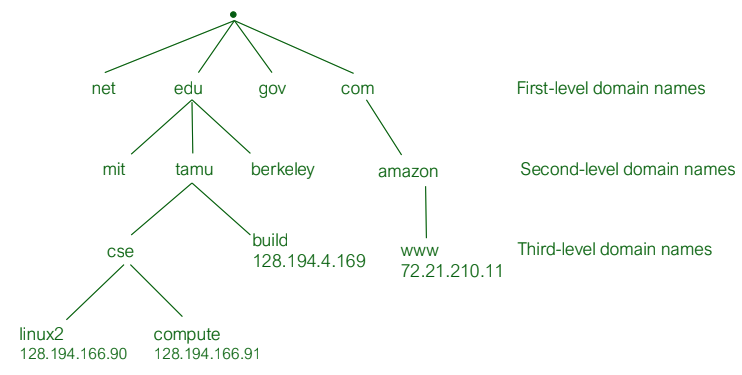
- The Internet maintains a mapping between IP addresses and domain names in a huge worldwide distributed database called DNS.
- Conceptually, programmers can view the DNS database as a collection of millions of
addrinfostructures.
Notes:
- The Distributed Database: The Domain Name System (DNS) is a massive, worldwide distributed database. It is not hosted on a single server; rather, it is divided hierarchically. Top-Level Domains (TLDs) like
.eduor.comsit at the top. Organizations (like TAMU) own and manage their specific sub-spaces (e.g.,tamu.edu). - A Programmer's View: Conceptually, a network programmer can view the entire DNS system as a giant collection of
addrinfostructures waiting to be queried.
Querying DNS
Domain Information Groper (dig) provides a scriptable command line interface to DNS
Lots of web interfaces (google "domain information groper")
unix> dig +short linux2.cse.tamu.edu
128.194.166.90

unix> dig +short -x 128.194.166.90
linux2.engr.tamu.edu.
linux2.cse.tamu.edu.
linux2.cs.tamu.edu.

unix> dig +short www.google.com
142.250.114.104
142.250.114.99
142.250.114.106
142.250.114.147
142.250.114.105
142.250.114.103
Notes:
- Manual Querying (
dig): You can manually query the DNS database from your terminal using thedig(Domain Information Groper) command. When you askdigto resolve a name to an IP address, you are querying for its A record.- There are different records for DNS
Example:
> dig linux2.cse.tamu.edu

; <<>> DiG 9.10.6 <<>> linux2.cse.tamu.edu
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 53704
;; flags: qr aa rd ra; QUERY: 1, ANSWER: 1, AUTHORITY: 3, ADDITIONAL: 5

;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1220
;; QUESTION SECTION:
;linux2.cse.tamu.edu.           IN      A

;; ANSWER SECTION:
linux2.cse.tamu.edu.    3600    IN      A       128.194.166.90

;; AUTHORITY SECTION:
cse.tamu.edu.           3600    IN      NS      csce-info-grid.net.tamu.edu.
cse.tamu.edu.           3600    IN      NS      wemr-info-dhcp.net.tamu.edu.
cse.tamu.edu.           3600    IN      NS      csce-info-dhcp.net.tamu.edu.

;; ADDITIONAL SECTION:
wemr-info-dhcp.net.tamu.edu. 3600 IN    A       128.194.211.237
csce-info-grid.net.tamu.edu. 3600 IN    A       165.91.16.132
csce-info-dhcp.net.tamu.edu. 3600 IN    A       128.194.169.147
csce-info-dhcp.net.tamu.edu. 3600 IN    A       165.91.16.135

;; Query time: 12 msec
;; SERVER: 128.194.254.1#53(128.194.254.1)
;; WHEN: Wed Apr 08 14:21:12 CDT 2026
;; MSG SIZE  rcvd: 227
- Cashing happens, and it is how we can control how frequent we want to respond
- Multiple IPs: As seen with the
google.comexample, querying a single domain name often returns multiple IP addresses. This is because large services use multiple servers for load balancing.
getaddrinfo - name -> ip mapping
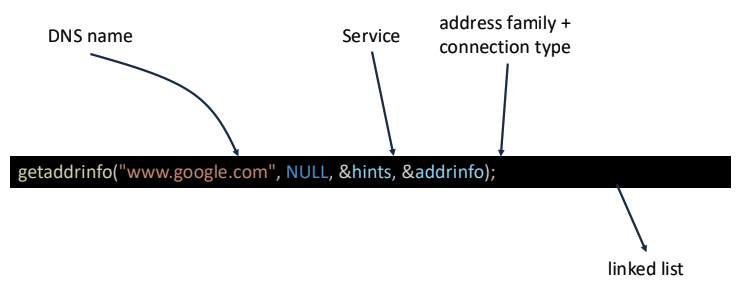
getaddrinfo("www.google.com", NULL, &hints, &addrinfo);
- DNS name
- Service
- address family + connection type
- linked list
Notes:
- Programmatic Resolution: While
digis for the command line,getaddrinfo()is the standard C function used to programmatically resolve a human-readable domain name into an IP address. - The Arguments:
- Host: The DNS name you want to resolve (e.g., "www.google.com").
- Service: The specific service or port (often set to
NULLif you only care about the IP). - Hints: A pointer to an
addrinfostruct that acts as a filter. You usehintsto tell the OS exactly what kind of addresses you want back (e.g.,AF_INETfor IPv4 only, andSOCK_STREAMfor TCP connections). - Result: A pointer that the OS will use to hand you back the results.
- The Linked List Return: Because a single domain name can resolve to multiple IP addresses (again, like Google),
getaddrinfodoes not return a single address. Instead, it dynamically allocates and returns a linked list ofaddrinfostructures. You must walk this linked list to try connecting to the IPs one by one.
Example:
// Get a list of addrinfo records
memset (&hints, 0, sizeof(struct addrinfo));
hints.ai_family = AF_INET;    // IPv4 only
hints.ai_socktype = SOCK_STREAM;    // Connections only
if ((rc = getaddrinfo(host, NULL, &hints, &lisp)) != 0) {
	fprintf(stderr, "getaddrinfo error")
	ecit(1);
}

// Walk your rc linked list
getaddrinfo
#include <sys/types.h>
#include <sys/socket.h>
#include <netdb.h>

struct addrinfo *addrinfo;
struct addrinfo hints;

memset(&hints, 0, sizeof(struct addrinfo));
hints.ai_family = AF_INET; /* IPv4 only */
hints.ai_socktype = SOCK_STREAM; / * Connections only */
getaddrinfo("www.google.com", NULL, &hints, &addrinfo);
Example:
- Basically this is the call
- Figuring out the why of the arguments might by difficult
Domain Naming System
Functions for retrieving host entries from DNS:
- getaddrinfo: query DNS using domain name or IP
getnameinfo: query DNS usingsockaddrstruct
struct addrinfo{
    int ai_flags;       /* flags for getaddrinfo */
    int ai_family;      /* address type(AF_INET or AF_INET6) */
    int ai_socktype;    /* the socket type */
    int ai_protocol;    /* the type of protocol */
    size_t ai_addrlen;  /* length of ai_addr */
    struct sockaddr *ai_addr; /* pointer to a sockaddr struct */
    char *ai_canonname;       /* the canonical name */
    struct addrinfo *ai_next; /* pointer to the next addrinfo struct */
};
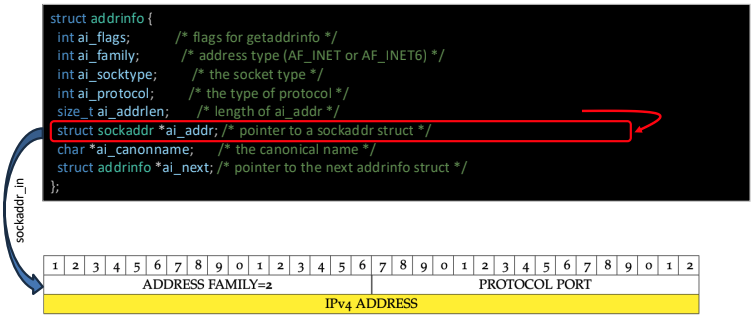
Notes:
- The
addrinfoStruct: The linked list returned bygetaddrinfois made up ofaddrinfostructs. This struct contains various metadata flags, but the most important field isai_addr. - Casting to
sockaddr: Theai_addrfield is a generic pointer to a socket address structure. To actually use this IP address in your C socket code (like passing it toconnect()), you must cast this pointer to asockaddrstruct (specificallysockaddr_infor IPv4). - The Reverse (
getnameinfo): If you already have asockaddrstruct containing an IP address and want to find its human-readable domain name, you use the reverse function:getnameinfo().
sockaddr = socket address
Base:
struct sockaddr {
	sa_family_t sa_family;
	char sa_data[14];
};
Derived:
struct sockaddr_in {
	short sin_family; // IPv4 or IPv6
	unsigned short sin_port; // port number
	struct in_addr sin_addr; // 32 bit IP
	char sin_zero[8];
};
Notes:
- We are only interested in
struct in_addr sin_addr;(32 bit IP).
HW1 Q1 - Networking
Problem 1
- Explain the difference between host byte order and network byte order. Why is this distinction important in socket programming?
- Little endian and Big endian
- Why is this distinction? We have to agree on a common format, when the receiver gets a bitstream, it can figure out where the address start and where they end, but it needs to know in what order to interpret them. The people who wrote the standard picked big endian.
- Consider a 32-bit integer with the value 0x12345678 on a little-endian machine. What is this value when the bytes are interpreted as if in network byte order? Which function would you use to convert it, and what is the function signature?
- In big endian it would be: 0x78563412
- Presentation will give you a byte stream
- If you wanted to store the TCP port number 8080 in a socket address structure for network transmission, how would you prepare it? Show the code using the appropriate byte-order conversion function.
- You are going to do
host to network short
- You are going to do
- True or False: You need to convert the IP address returned by inet_pton() to network byte order before placing it in a socket address structure. Explain your answer.
Try all of these questions!
Anatomy of an internet connection

Notes:
- The Connection 4-Tuple: To uniquely identify and maintain a network connection, the system needs exactly four pieces of information: the Client IP, the Client Port, the Server IP, and the Server Port.
- Client vs. Server Ports: In the networking API, services are identified by a 16-bit port number.
- Server Side: Must use a "well-known" port (e.g., 80 for HTTP) so that clients always know exactly where to send their requests.
- Client Side: Does not need a specific port. When a client initiates a connection, the OS kernel automatically assigns it a random, available port number.
- Multi-homed Clients: If your client machine has multiple Network Interface Cards (NICs) connected to different networks, your socket's source IP address will automatically bind to the specific interface the OS uses to route the outbound connection.
If you look at /etc/services you will see that http is defined as 80/tcp:
cat /etc/services | more
...
http 80/udp www www-http # World Wide Web HTTP
http 80/tcp www www-http # World Wide Web HTTP
...
- When a client makes a connection to a service it is identified by a port number, the network API is such that if you require a port number, your kernel will give you a random port number.
- The client could also be multi-home (have multiple network interface cards), if your connection is going out of an specific interface, your socket's IP address will get bound to that specific interface IP address.
- What we care about is that a connection has the following
- Client IP and client port
- Server IP and server port
- On the server side you could have many different services running, which you can identify by the port number!
Using Ports to Identify Services

Notes:
- Layer 3 vs. Layer 4: Remember that an IP address (Layer 3) only gets a packet from one host machine to another. It is the transport layer (Layer 4) that uses the port number to figure out which specific service on that machine should receive the data.
- Kernel Demultiplexing: Because the Layer 4 header is embedded inside the Layer 3 IP header, the kernel can inspect incoming packets. If a packet arrives with a destination port of 80, the kernel routes that packet's payload directly to the web server process listening on port 80.
Servers
Servers are long-running processes (daemons)
- Created at boot-time (typically) by the init process (process 1)
- Run continuously until the machine is turned off
Each server waits for requests to arrive on a well-known port associated with a particular service
- Port 23: telnet server
- Port 25: mail server
- Port 80: HTTP server
A machine that runs a server process is also often referred to as a "server"
Notes:
- Daemons: Server processes are typically "daemons"—long-running background processes that run continuously until the machine is shut down.
- Boot-time Creation: Historically, a special process called
init(Process ID 1) is responsible for automatically launching these services at boot time so they are always available. However, under the hood, they are just regular user-space programs that configure themselves to wait for incoming traffic. - Well-Known Ports: Each daemon waits for requests on a universally agreed-upon port (e.g., 23 for Telnet, 25 for Mail, 80 for HTTP). Note: The term "server" is interchangeably used to describe both the software process and the physical machine running it.
Server examples
Web server (port 80)
- Resource: file serv/compute (CGI programs)
- Service: retrieves files and runs CGI programs on behalf of the client
FTP server (20, 21)
- Resource: files
- Service: stores and retrieve files
Telnet server (23)
- Resource: terminal
- Service: proxies a terminal on the server machine
Mail server (25)
- Resource: email "spool" file
- Service: stores mail messages in spool file
Notes: See /etc/services for a comprehensive list
of the services available on a UNIX machine
Notes:
- This is basically where the symbolic name of a service is mapped to a port number
- By convention we have already a lot of pre-defined port numbers: Port Numbers Cheat Sheet
Organization of an internet application

Notes:
- The Application Layer: Both the client process (e.g., your web browser) and the server process live in the user-space Application Layer.
- The Socket API: To communicate over the network, these user-space programs cannot touch the network hardware directly. Instead, they use the Socket API. By reading and writing to sockets, the applications invoke the kernel, which handles the complex tasks of framing the data into packets, adding headers, and independently routing them through the network link to the destination.
Network Programming with Sockets
- Sockets API
- An interface to the transport layer
- Introduced in 1981 by BSD 4.1
- Implemented as library and/or system calls
- An interface to the transport layer
Might see BSD Sockets: A Quick And Dirty Primer
Notes:
- This was done by one guy, a grad student at UC Berkley, way back in the early 80s
- It is the Application Interface of layer 4!
Stream sockets

-
"This is long"
Notes:
-
There are many kinds of protocols (i.e. tcp/udp)
-
But the cross-protocol types are mostly uniform
-
You somehow get a socket, on that socket, you send a byte stream (you can also do write), and you somehow are connected to the destination.
-
What you expect is that the same byte sequence would appear on the other end, but notice that between the sender and the receiver is a big homorphous cloud, it is possible that your first uplink cannot send a long message, so you are force to break this first uplink into other packets, this is where fragmentation happens (breaking up a long message into several smaller messages)
- What your tcp will try to do is to fragment into smaller packets so that they do not get further fragmented in other steps
-
The Byte Stream Abstraction: While there are many underlying network protocols (like TCP and UDP), the socket API provides a uniform interface. You obtain a socket and push a continuous stream of bytes into it, expecting the exact same sequence to emerge at the destination.
-
Fragmentation: In reality, the internet is a complex cloud with varying capacity limits. If your message is too long for a network uplink, the network stack forces fragmentation—breaking your large message into several smaller packets. These packets traverse the network and are reassembled by the receiving OS.
-
The "Short Read" Reality: Because data arrives in fragmented packets over unpredictable times, calling
read()on a socket will very likely result in a short read. Even if you ask for 1000 bytes, the kernel might only return the 200 bytes it has received so far. As a programmer, you must anticipate this and usually read in a loop until you have all your expected data.
Binding a socket?
- Each wall represents a NIC (local IP)
- Each socket represents a port
- Binding
plugging into a chosen (IP, port)
Notes:
- What is a socket? A socket is simply a kernel data structure that acts as an abstraction for a networking endpoint.
- What is binding? When you first create a socket, it is "free-hanging" and useless. Binding is the process of formally assigning that socket to a specific local IP address (representing a physical Network Interface Card) and a specific 16-bit port number.
A Server-Client interaction in TCP - POSIX functions

Notes:
- This is the one thing to remember in TCP/IP networking!
- The client and the server are asymmetrical, the server needs to comes up first before a client can connect to it
- Server
- The way a server comes up is that it creates a socket, once you have this free hanging socket, it needs to be binded to a specific address and port number
- At this point you have taken over this port number and associated to an IP address
- If you are a multi-home host, you want to bring up a service, you first create a socket, then you bind it first to a particular interface, and then to a particular port
- Most often you will bind to
0.0.0.0(any interface), but you could also specify an ISP or something, then nobody from other network interface will be able to connect to it.
- Most often you will bind to
- Then the server puts this socket into passive mode, in this passive mode it can accept connections
- Then it specifies to "make me a queue of n long" (i.e. up to 5 outstanding connections) - 5 clients possible, we do this by calling
listen(). - Have up to 5 guys to wait.
- Then it specifies to "make me a queue of n long" (i.e. up to 5 outstanding connections) - 5 clients possible, we do this by calling
- Then you accept the connection using
accept()- at this point the connection is either waiting, or connected
- Returning from
accpet()will provide a new socket, that socket will directly connect you to. - This is the socket that will give you direct connection to the client!
- Every time a new connection is formed you get a new socket.
- Now you have a bi-directional stream between the client and the server
- Note the client only has one socket.
- The way a server comes up is that it creates a socket, once you have this free hanging socket, it needs to be binded to a specific address and port number
- Client
- The client creates a socket and just connects to it.
- It specifies the server's IP address and port number
- When the connect returns successfully, that socket connects to the socket that was return by the
accept()on the server
- The server can do send and receive (read and write), and you can also do send and receive (read and write)
- These have added functionality like sending messages out-of-bound, but otherwise they work basically the same
- The client creates a socket and just connects to it.
Rewritten notes:
- The Golden Rule of TCP: TCP/IP communication is strictly asymmetrical. The server must be completely initialized and waiting before a client can attempt to connect.
- The Server Lifecycle:
socket(): Create the initial socket.bind(): Claim an IP address and port number. (Often, servers bind to0.0.0.0to accept connections from any available network interface).listen(): Put the socket into "passive mode." This tells the kernel to stop acting like a client and instead queue up incoming connection requests (the "backlog").accept(): The server blocks and waits for a client to connect. Crucial concept: When a client connects,accept()returns a brand new socket. This new socket gives you a direct, bi-directional stream to the client, while the original passive socket goes back to listening for more clients.
- The Client Lifecycle:
socket(): Create a single socket.connect(): Specify the target server's IP and port. Once it succeeds, it connects directly to the new socket generated by the server'saccept().
- Communication: Once connected, both sides can use standard
read()andwrite()(or network-specificsend()andreceive()) to talk to each other.
Accepting a new connection

Notes:
- A new connection arrives
- Your switchboard operator is basically going to connect the incoming connection to you but the operator first calls you: "are you ready to accept this connection"
- You get another phone and you are now get connected to a copy of your phone
- Every time a connection is made you have a new phone which connects to the call
Echo Server: accept illustrates

Notes:
- Usually the kernel picks a random port number for the client
- The connection is made, when this new connection is made, the server gets a socket, and the passive socket remains free for accepting more connections.
Function: socket
int socket(int family, int type, int protocol)
- Create a socket.
- Returns file descriptor or -1. Also sets
errnoon failure. family: address family (namespace)- AF_INET for IPv4
type: style of communication- SOCK_STREAM for TCP (with AF_INET)
protocol: protocol within type- typically 0
- Returns file descriptor or -1. Also sets
Notes:
- When we create a socket we specify an address family, this is saying what type of addresses the socket is made for
- For us the only thing we are interested in is IPv4
- The type is basically saying a style of communication
- TCP/UDP, etc.
- You can leave the
protocolto be 0, and the API will pick the communication type for you - Now we have a socket, but this socket is free floating, it is useless right now, it is just some data structure in the kernel
Example: socket
int sockfd, new_fd; /* listen on sock_fd, new connection on new_fd */
struct sockaddr_in my_addr; /* my address */
struct sockaddr_in their_addr; /* connector addr */
int sin_size;

if((sockfd = socket(AF_INET, SOCK_STREAM, 0)) == -1) {
    perror("socket");
    exit(1);
}
Notes:
- The way that a socket is exposed to you in your program is as a file descriptor
- You can basically make it look like a file (doing read and writes on it), and then you can do more advanced stuff like sends and receives.
Function: bind
int bind(int sockfd, sockaddr* myaddr, int addrlen)
- Bind a socket to a local IP address and port number
- Returns 0 on success, -1 and sets
errnoon failure sockfd: socket file descriptor (returned from socket)myaddr: includes IP address and port number- IP address: INADDR_ANY ⇒ all IP addrs
- port number: set by kernel if 0 , else set by caller
addrlen: length of address structure= sizeof(struct sockaddr_in)
- Returns 0 on success, -1 and sets
Notes:
- For us the socktype of
sockaddris the one for IPv4 - This family is basically the same as the address family of the socket
- We create a structure of type
sockadr_in, and just cast that tosockaddr - The
intis just saying how big of a data - When bind returns, your socket is now bound to an IP address and port number
- If you specify
INADR_ANY, you allow connections coming from every interface in your server infrastructure.
Function: listen
Put it in passive mode
int listen(int sockfd, int backlog)
- Put socket into passive state-wait for connections rather than initiate a connection
- Returns 0 on success, -1 and sets
errnoon failure sockfd: socket file descriptor (returned fromsocket)backlog: bound on length of un"accept"ed connection queue (connection backlog);- kernel will cap, thus better to set high
- Returns 0 on success, -1 and sets
Example:
if (listen(sockfd, BACKLOG) == -1) {
    perror("listen");
    exit(1);
}
Notes:
- If you expect a lot of connections, you want those connections to hang for the server to be able to serve when it comes available
- With listen you also put the socket in passive mode
Function: accept
int accept(int sockfd, sockaddr* cliaddr, int* addrlen);
- Block waiting for a new connection
- Returns file descriptor or -1 and sets
errnoon failure sockfd: socket file descriptor (returned fromsocket)cliaddr: IP address and port number of client (returned from call)addrlen: length of address structure = pointer tointset tosizeof(struct sockaddr_in)
- Returns file descriptor or -1 and sets
addrlenis a value-result argument- the caller passes the size of the address structure, the kernel returns the size of the client's address (the number of bytes written)
Notes:
- Give me the IP and port number of the client
- For us we are only interested with IPv4, so
sockaddrwill only besockaddr_in
Function: connect
int connect (int sockfd, sockaddr* servaddr, int addrlen)
- Connect to another socket.
- Returns 0 on success, -1 and sets
errnoon failure sockfd: socket file descriptor (returned fromsocket)servaddr: IP address and port number of serveraddrlen: length of address structure= sizeof (struct sockaddr_in)
- Returns 0 on success, -1 and sets
Notes:
- This is what the client uses to connect to the server
- If your connect returns successfully, then this file descriptor is now connected to the server, and now you can do read and write
Example server code (tcp-echo-server)

int main (int argc, char *argv[]) [
    int port = atoi(argv[1]);

    int server_fd, client_fd, err;
    struct sockaddr_in server, client;
    char buf[BUFFER_SIZE];

    server_fd = socket(AF_INET, SOCK_STREAM,0);

    server.sin_family = AF_INET;
    server.sin_port = htons(port);
    server.sin_addr.s_addr = htonl(INADDR_ANY);

    int opt_val = 1;
    setsockopt(server fd, SOL SOCKET, SO REUSEADDR, &opt val, sizeof opt val);
    bind(server_fd, (struct sockaddr *) &server, sizeof(server));

    listen(server_fd, 128);
    printf("Server is listening on %d\n", port);

    while (1) {
        socklen t client len = sizeof(client);
        client_fd = accept(server_fd, (struct sockaddr *) &client, &client_len);

        if(client_fd < 0) on_error("Could not establish new connection\n");
        while (1) {
            irf{ read = recv(client_fd, buf, BUFFER_SIZE, 0);

            if (!read) break; // done reading
            if (read < 0) on_error("Client read falled\n");

            send(client_fd, buf, read, 0);a
        }
    }

    return 0;
}
Notes:
- First creates a socket -> gets TCP socket
- Specifies address family (i.e. IPv4) ==
AF_INET? - For us it is basically
SOCK_STREAM(which means tcp), and the 0 means that we are using the default implementation for that type of communication
- Specifies address family (i.e. IPv4) ==
- Then it binds the socket to your local endpoint
- We are binding it to all/any our network interfaces
- As a result you get a file descriptor in your file descriptor table
- Then the server puts the socket into passive mode with
listen()- In this example, the 129th connection will be dropped
- Then it
accepts()a connection and gets a client file descriptor- "Give me the address of the client that is connecting to me"
- You can now parse this
socketaddrand figure out the connection - You get a new descriptor in your file descriptor table that is connected directly to the client.
- Then we can normally use this file descriptor to read and write to!
- receive is basically like read and send is basically write and you can use all 4 of them to write to socket file descriptors.
- Test it using
telnet(a client)telnet localhost 9999
Example client code (tcp-client)

int main(int argc, char *argv[]) {
    char *ip = argv[1];
    int port = atoi(argv[2]);
    int sock;
    struct sockaddr_in addr;
    socklen_t addr_size;
    char buf[BUFFER_SIZE];
    int err, n;

    spck = socket(AF INET, SOCK STREAM,0);
    if (sock < 0) on_error("Could not create socket.\n");

    memset(&addr, 0, sizeof(addr));
    addr.sin_family = AF_INET;
    addr.sin_port = htons(port);
    addr.sin_addr.s_addr = inet_addr(ip);

    if(connect(sock, (struct sockaddr*)&addr, sizeof(addr)) < 0)
        on_error("Failed to connect.\n");
    printf("Connected to the server.\n");

    while (1) {
        // read & write from sock
    }

    close(sock);
    return 0;
}
Notes:
- What the client does is:
- Creates a socket, but does not bind it to an end point, it just does a
connect- Connect this socket to this remote address
- Backend the host and the port (convert to ip with
inet_addr) - Once it returns we can read and write from the socket
TCP Connection Example

Notes:
- The 32-bit Sequence Number Space: To manage the chaotic network "cloud" where packets get lost or arrive out of order, TCP uses a 32-bit sequence number space to track every single byte of data sent over the connection.
- Initial Sequence Numbers (ISN): When a client initiates a connection, it doesn't start counting at zero. It picks a random 32-bit sequence number (let's call it
r1) and tells the server, "I am going to start sending you data starting at offsetr1". - Detecting Lost Packets (Holes): As the server receives data, it keeps track of the sequence numbers. If it receives bytes up to
r1 + 50, the next byte it expects isr1 + 51. If the next packet it receives starts atr1 + 100, the server instantly knows there is a "hole" in the data stream (missing packets). It will then ask the client to retransmit those missing bytes, which is the core mechanism that provides TCP reliability. - Bi-Directional Reliability: TCP is a two-way (full-duplex) protocol, meaning data flows in both directions. Therefore, the server must also pick its own random starting sequence number (
r2) and share it with the client. This allows the client to track the server's byte stream and detect if any of the server's packets are lost in transit. - The Asymmetrical Reality: This entire connection handshake relies on the asymmetrical nature of TCP. The server must already be running and in the
listenstate before the client can send its initialr1sequence number. When the server callsaccept(), it completes the connection and receives all these critical tracking details.
Example: writen

/* Write "n" bytes to a descriptor */
ssize_t writen(int fd, const void *ptr, size_t n) {
    size_t nleft;
    ssize_t nwritten;
    nleft = n;
    while (nleft > 0) {
        if ((nwritten = write(fd, ptr, nleft)) < 0) {
            if (nleft == n)
                return(-1); /* error, return -1 */
            else
                break; /* error, return amount written so far */
        }
        else if(nwritten == 0)
            break;
        nleft -= nwritten;
        ptr += nwritten;
    }
    return(n - nleft); /* return >= 0 */
}
Notes:
- The Short Write Problem: When working with network sockets, the OS does not guarantee that a single
write()system call will transmit all the bytes you asked it to. If the network buffer fills up, it might only send a portion of your data (a "short write"). - The while Loop Solution: To fix this, you must build a custom wrapper function (like
writen). It uses awhileloop to repeatedly callwrite()as long as there are bytes left to send (nleft > 0). - Pointer Math: With each successful loop iteration, you subtract the number of bytes written from
nleft, and advance the memory pointer (ptr += nwritten) so the nextwrite()picks up exactly where the last one left off. - Error Handling: If the loop fails on the very first try, it returns an error (
-1). If it manages to write some bytes before failing, it breaks out of the loop and safely returns the total number of bytes successfully written so far.
Example: readn

/* Read "n" bytes from a descriptor */
ssize_t readn(int fd, void *ptr, size_t n) {
    size_t nleft;
    ssize_t nread;
    nleft = n;
    while (nleft > 0) {
        if ((nread = read(fd, ptr, nleft)) < 0) {
            if (nleft == n)
                return(-1); /* error, return -1 */
            else
                break; /* error, return amt read */
        }
        else if(nread == 0)
                    break; /* EOF */
            nleft -= nread;
            ptr += nread;
    }
    return(n - nleft); /* return >= 0 */
}
Notes:
- The Short Read Reality: Just like writes, network reads are notorious for "short reads" because data arrives in fragmented packets over the internet. If you ask for 1000 bytes, you might only get 200 right now.
- Accumulating Data: The
readnfunction acts exactly likewritenbut in reverse. It loops continuously, callingread()and advancing the buffer pointer until it has successfully pulled allnrequested bytes from the socket. - Handling EOF: If
read()ever returns0, it means you have reached the End of File (the connection closed). The loop immediately breaks and returns whatever bytes it managed to read before the connection dropped.
Server: setsockopt()
The socket can be given some attributes
...
/* Eliminates "Address already in use" error from bind(). */
if (setsockopt(listenfd, SOL_SOCKET, SO_REUSEADDR,
        (const void *) &optval , sizeof optval) == -1)
    return -1;
Handy trick that allows us to rerun the server immediately after we kill it
- Otherwise, we would have to wait about 15 secs
- Eliminates "Address already in use" error from
bind()
Strongly suggest you do this for all your servers to simplify debugging
Notes:
- The "Address already in use" Error: When you kill a server process, the OS doesn't instantly free up its port. It temporarily reserves it (often for a few seconds to a couple of minutes) to catch any lingering, delayed network packets from the old connection. If you try to quickly restart your server and
bind()to the same port, it will fail. - The SO_REUSEADDR Fix: You can bypass this annoying delay by using the
setsockopt()system call to give your socket a special attribute calledSO_REUSEADDR. - Debugging Convenience: Setting this flag tells the kernel to let you instantly re-bind to the port, ignoring any lingering packets. This is highly recommended for all your server code to make debugging and restarting painless.