10 - File System Organization
Class: CSCE-313
Notes:
Outline
- File System Abstraction
- File System Organization
- UNIX File API
- Hard links vs. soft links
File System Abstraction
The file system abstraction
- Named hierarchical data: Human-readable names (e.g., filenames) given to data
- Reliability: Unexpected power-cycles should not corrupt data
- E.g., to create a new file, you need to do operations atomically
- Allocate an inode for the file
- Allocate data blocks to the file
- Write the block ids into the file inode
- Read data for directory, modify, write back data for dir
- Controlled sharing: Determine who can read/write/execute certain files sequentially/simultaneously w/o corrupting
Notes:
- It gives you main hierarchical data
- All that you have on a disk are tracks and sectors
- In some sense you have a linear sequence of sectors
- Think of it as counting from the inside to the outside
- Somehow your filesystem is going to construct a hierarchical namespace out of this linear structure
- This gives you abstraction to be able to organize your files well
- But under the hood it is just a linear structure mapping

- On disk, the green blobs represent inodes
- The red and blue blobs represent data blocks for the two inodes corresponding to a & b.
Example:
- Imagine that you are trying to create a new file:
- consider what you filesystem needs to do
- The entire metadata for a file goes into an inode
- The entire sequence of bytes will go to that inode
- Once an inode is allocated, it needs to mark an inode as unavailable
- It has to go search for and find free data blocks to assign to that inode, and then it needs to write the entry for that file into a directory
- An entry is nothing more than inode-name pairs
- It better not fail anything in between, it better do this atomically, because otherwise you will need to use
fseekingto recover your filesystem which takes a lot of time
- Your filesystem not only is building this hierarchical abstraction, but it is doing it very reliable and giving you the illusion of all or nothing meaning either this things all happen or none of it happen.
- Somewhere in the file metadata is our permission bits that allow someone to read/write, etc.
- Somehow if you try to reach a particular file, you need to be able to go from the directories on top of it (from
/tofooand then fromfootoa) - Your filesystem looks up that inode, and in that inode tells you the exact sequence of disk blocks corresponding to that file, and now you can read the exact blocks in order to read the file.
- For you it is just a byte offset within the file, but underneath, the system is reading blocks and returning bytes to you
An example data layout on disk
Consider the disk to be a linear sequence of blocks.
- Say that block size is 4 KB . Gives us a 256 KB disk.
- The blocks are addressed from
.

Notes:
- For the point of view of the filesystem, think of this space as a linear array
- Enture filesystem is 256 KB
- Filesystem will layout metadata in different places which will let it build a hierarchical space
- This is actually very close to how the original UNIX filesystem was layed out
Data region in a file system
-
Reserve data region to store user data

-
File system has to track which data blocks belong to a file, and which blocks are free.
-
Track metadata for a file such as its size, mode bits, owner, etc. (inode)
How do we store these inodes in the file system?
Notes:
- When a file system is created (formatted), it strictly divides the linear disk blocks into different regions: a large Data Region for actual file contents, and a smaller metadata region called the Inode Table.
- The total number of inodes is fixed at the exact moment the file system is created. Because every single file requires exactly one inode, this establishes a hard limit on the maximum number of files the system can hold.
- The filesystem has figured out somehow that it is going to take 58 blocks and allocate data for files and other objects to be layed out on those 58 blocks, and then keep 8 blocks for metadata
- Now your filesystem needs to split this up into metadata (inodes) and other things.
Inode table in a file system
- Reserve some space for an inode table (array)
- This holds an array of on-disk inodes.
- Ex) inode tables: blocks 3-7, inode size: 256 bytes
- A 4-KB block can hold 16 inodes.
- This file system contains
inodes. (maximum number of files)

Notes:
- The Design Trade-off: You must balance the ratio of inodes to data blocks based on what you are storing:
- Scenario A (Wasted Space): If you format the disk with millions of inodes, but only store a few massive 4K video files, you waste gigabytes of disk space on empty, unused inodes.
- Scenario B (Out of Inodes): If you format the disk with too few inodes, but store millions of tiny 1 KB text files, you will run out of inodes. When this happens, the OS will throw a "Disk Full" error and prevent you from creating new files, even if you have plenty of empty data blocks left.
- The Math: In the slide's example, the OS knows an inode is 256 bytes. A standard 4 KB (4096 bytes) block can hold exactly 16 inodes (4096/256=16). If the file system reserves 5 blocks for the table, the absolute maximum capacity of this file system is 80 files (16×5=80).
Allocation Structures
- To track whether inodes or data blocks are free or allocated.
- Use a bitmap, each bit indicates free(0) or in-use(1)
- data bitmap: for data region (per block)
- inode bitmap: for inode table (per inode)

Notes:
- To manage the disk efficiently, the file system uses two specific bitmaps (arrays of bits where
0means free and1means in-use): a Data Bitmap and an Inode Bitmap. - Design Trade-off (Bitmaps vs. Linked Lists): You could track free data blocks using a simple linked list (where one free block holds a pointer to the next free block). However, this is terrible for spatial locality. If you need to add a new block to a growing file, the next free block in the linked list might be physically located on the other side of the disk. This forces the mechanical disk head to perform a "seek," which is extremely slow (taking about 10ms).
- The Bitmap Advantage: By using a bitmap instead of a linked list, the OS can easily scan the array for a sequence of adjacent
0s. This allows the OS to allocate contiguous blocks for a file, ensuring the file's data stays physically close together on the platter so the disk head barely has to move, dramatically improving read/write speeds.
Super Block
- The Super block contains metadata about this file system
- Ex) The number of inodes, beginning location of inode table etc.

- Thus, when mounting a file system, the OS/FS reads the superblock first to initialize various information.
Notes:
- The Super Block acts as the "master metadata" record for the entire file system partition. It stores the global blueprint of the disk, such as the total number of inodes, total data blocks, and the exact physical locations of the inode table and bitmaps.
- The Mount Process: When you attach (mount) a drive to your computer, the OS must read the Super Block first to initialize itself. Without it, the OS wouldn't know how to navigate the disk's structure.
- The Root Dependency: Most importantly, the Super Block helps the OS figure out how to locate the inode for the root directory (
/). The OS absolutely needs this root inode because all absolute paths (like/home/user/file) start from the root. Once the OS finds the root inode, it can successfully attach the disk to your hierarchical namespace and begin traversing folders.
File Organization
The inode
- Each inode is referred to by an inode number.
- From an inode #, the FS can compute the location of inode on disk.
- Ex) inode number: 32
- Calculate the offset into the inode region (
sizeof(inode) (256 bytes) - Add start address of the inode table
inode region
- Calculate the offset into the inode region (

Notes:
- The Inode Array (O(1) Lookup): To the file system, the inode table is just a massive, flat array of fixed-size data structures. This means finding a file's metadata doesn't require "searching" the disk; it is a direct mathematical calculation using the inode number as an index.
- Calculating the Byte Offset: To find exactly where an inode lives, the OS multiplies the given inode number by the size of an inode (e.g., 256 bytes). For inode 32, the offset is 32×256=8192 bytes (8 KB). It then adds this offset to the known starting address of the inode table to find the physical location.
- Calculating the Block Location: Because disk reads happen in blocks (e.g., 4 KB), the OS needs to know which specific block to load into memory. If one 4 KB block holds 16 inodes, you find the exact block by taking the integer division of the inode number by 16. The remainder (modulo) of that division tells the OS exactly which of the 16 slots within that loaded block contains your specific inode.
File System Layout
How do you build a hierarchy (tree) of files from the flat model of data blocks?

Notes:
- The Flat Reality vs. The Hierarchical Illusion: On the hardware level, everything is just a long array of inodes and data blocks. The familiar "folder tree" hierarchy is purely a software construct built by the Operating System.
- The Root & The Superblock: The entire tree stems from the Root Directory (
/). The file system's Superblock contains the master pointer to this root inode, providing the mandatory starting point for all absolute path traversals. - What is a Directory, Really? A directory is simply a special file. Its underlying data is nothing more than an enumeration (a list) of pairs: (Human-readable Name → Inode Number).
- The Crucial Insight (Where are names stored?): A file's name is not stored inside the file itself, nor is it stored inside the file's inode. The name of a file only exists inside the data of its parent directory. This is exactly why you can have multiple different names (hard links) pointing to the exact same file/inode.
- Path Resolution (The Chain): To access a nested file like
/a/c/e, the OS must traverse the chain. It reads the root to finda's inode, readsa's directory data to findc's inode, and readsc's directory data to finally gete's inode. The fileeeffectively doesn't exist outside the context ofc.- In this example
- a has two names and inode numbers:
- b -> object
- c -> directory
- c is just an enumeration of names and inode numbers
- d -> object
- e -> object
- c is just an enumeration of names and inode numbers
- a has two names and inode numbers:
- In this example
Characteristics of a magnetic disk

Why are magnetic disks slow?
- Platters rotate at a constant speed.
- Each surface has data in the form of several tracks.
- Each track is separated into sectors/blocks.
How a block is read from disk
- The arm moves the disk head to the right track. This is a "seek". Extremely slow
. - Then, the head waits for the correct sector to come below. This is relatively faster because of constant motion (<<10 ms), determined by disk RPM.
- Read the sector and send to the CPU. Much faster (SATA rate:
).
Notes:
- If you want to read something off a particular sector, then the head first needs to reach that track. You will spend 10ms on this.
- The blocks of a file needs to be layed out in such a way that you are able to quickly reach each block without watining too much for the disk to move
- Look at The Memory Hierarchy for disk r/w time calculations
- It is just slow to move a mechanical thing
- Once you get to a position in the disk, then you can read very rapidly
Building a hierarchy
- Files: "contain" metadata and actual data
- Directories: Special files that contain names and "pointers" to files

- In some sense you are force to go from a known thing to the target file
Filesystems terms
- path: string identifying a file (e.g.,
/home/davidkebo/labs/main.cpp)- Think of it as having a "
/"
- Think of it as having a "
- root directory: top-most directory in the filesystem, denoted by "
/"- Unlike Windows
- absolute path: path starting from the root "
/" - relative path: a path relative to the current working directory. Does not start with a "
/"- The kernel keeps track of your current working directory
- index node (inode): structure that stores the file/directory attributes such as the object's metadata and the data block locations on disk.
- Read it using "
stat" - The entire sequence of blocks to read that file is somehow packed into that inode
- Read it using "
- hard link: a directory entry that refers to the inode of a file.
- Basically makes a new name for the same inode
- soft/symbolic link: a shortcut that names a path to the file
- Really just a path name embedded in this special object called symlink
- Does not have to be a path (it can be any string), but during resolution, it starts resolving using the path that the symlink corresponds
hard link vs. soft link

Notes:
- Hard Links (Direct Inode Mapping):
- A hard link is simply a new directory entry that maps a human-readable name directly to an existing inode number.
- When you create a hard link, you aren't creating a "shortcut"—you are creating a full, "first-class" name for the exact same file. The OS cannot tell which name was the "original."
- Reference Counting: The inode maintains a reference count of how many hard links (names) point to it. When you run a command like
rmto remove a file, you are actually just unlinking that specific name and decrementing the reference count by 1. - Deletion: The actual file data and inode are only erased from the disk when the reference count reaches 0.
- Restrictions: To prevent corrupting the file system structure, you cannot create a hard link to a directory, and you cannot create a hard link to a symlink.
- Soft Links / Symbolic Links (Path Shortcuts):
- A symlink is a completely separate, special type of file with its own unique inode.
- Instead of pointing directly to the target's inode, the underlying data inside a symlink file is literally just a text string containing the path to the target.
- Dangling Links: Because it only stores a path string, if you delete the original target file, the symlink still exists but points to nothing. If you try to open it, the path resolution will fail.
- Storage Optimization: If the target's path string is very short, the file system will optimize performance by storing the string directly inside the symlink's inode itself. If the path name is too long, the file system will allocate actual data blocks to the symlink's inode just to store the string.
- Flexibility: Unlike hard links, symlinks can point to directories, can point to non-existent names, and can even link across entirely different file systems/partitions.
Hard link example:
> ln foo.md bar.md
> ls -li foo.md bar.md
69312997 -rw-r--r--  2 macc  staff  0 Mar 18 14:37 bar.md
69312997 -rw-r--r--  2 macc  staff  0 Mar 18 14:37 foo.md
- Note the two arguments to give is the existing name and the new name you want to give
- They will both point to the same filesystem object
- Note this is very different than doing a deep/shallow copy of an object, here we are talking about the same inode!
Soft link example:
> ln -s foo.md fib.md
> ls -li foo.md fib.md
69313223 lrwxr-xr-x  1 macc  staff  6 Mar 18 14:38 fib.md -> foo.md
69312997 -rw-r--r--  2 macc  staff  0 Mar 18 14:37 foo.md
Links
Hard link
- Directory entry contains the inode number
- Creates another name (path) for the file
- Each is "first class"
Soft link or Symbolic link
- Directory entry contains the inode number
- The data "logically" contained in the file corresponding to this inode is a pathname
- Either the pathname fits entirely in the inode, or
- It's in the data block(s) for the inode
Hard Links

shell command
ln /dirA/name1 /dirB/name2
is typically implemented using the link system call:
#include <stdio.h>
#include <unistd.h>

if (link(“/dirA/name1”, “/dirB/name2”) == -1)
perror(“failed to make new link in /dirB”);
- Cannot hard link to a directory.
- Cannot hard link to a sym link.
- The symlink is automatically traversed

- inode #
-
links
Hard Links: refcounts

#include <stdio.h>
#include <unistd.h>

if (unlink(“/dirA/name1”) == -1)
perror(“failed to delete link in /dirA”);

if (unlink(“/dirB/name2”) == -1)
perror(“failed to delete link in /dirB”);
File System Organization

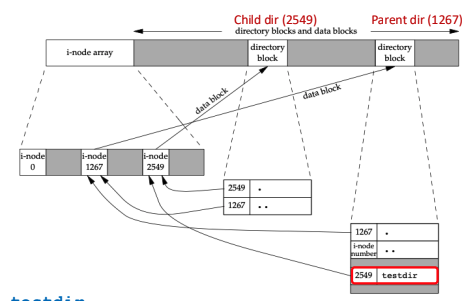
After $mkdir testdir
- i-node 2549 has a type "directory" and a link count of 2.
- Any leaf directory (a directory that does not contain any other directories) always has a link count of 2.
- The value 2 comes from the directory entry that names the directory (
testdir) and from the entry for dot (.) in that directory.
Symbolic (Soft) Links
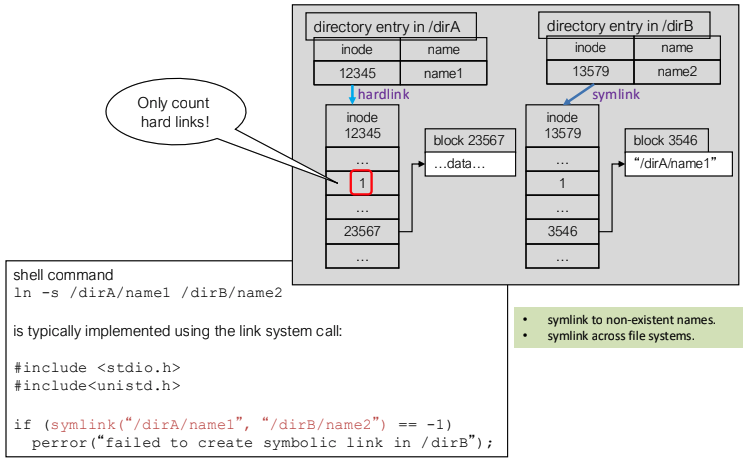
- symlink to non-existent names.
- symlink across file systems.
Links: example
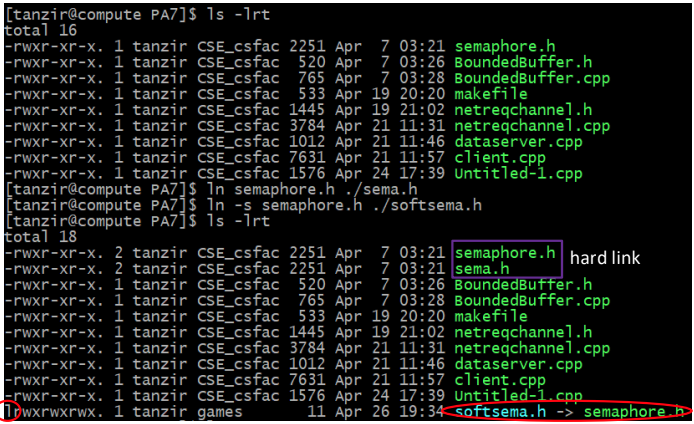
File system "Tree"
hard link: The mapping between the name and the underlying file
- There can be multiple hard links to the same file (e.g., shortcuts).
- Means that the directory tree is not always a tree.
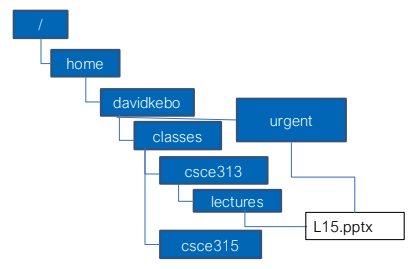
$ ln <existing file> <link>
UNIX Directory API
Current Directory
#include <unistd.h>

char * getcwd(char * buf, size_t size);
/* get current working directory */
Example:
void main(void) {
    char mycwd[PATH_MAX];
    if (getcwd(mycwd, PATH_MAX) == NULL) {
        perror ("Failed to get current working directory");
        return 1;
    }
    printf("Current working directory: %s\n", mycwd);
    return 0;
}
Notes:
- It is convenient to allocate a buffer of size
PATH_MAXbecause UNIX will restrict you to path names that do not exceed this maximum
Open, Read, Close
Read is stateful with a cursor.
Reading the same directory again gives back the next file in the directory.
#include <dirent.h>
int main(int argc, char * argv[]) {
    struct dirent *direntp;
    DIR *dirp = opendir(argv[1]);
    while((direntp = readdir(dirp)) != NULL)
        printf("%s\n", direntp->d_name);

    closedir(dirp);
    return 0;
}
Notes:
- The Directory Abstraction: Even though directories are technically just special files containing lists of mappings (names to inodes), UNIX strictly forbids you from opening them with a standard
open()andread()to access their raw bytes. This rule exists to prevent user programs from accidentally (or maliciously) corrupting the file system's core structure. - The DIR Handle: To read a directory, you must use the specific
opendir()system call. This gives you back aDIR*handle (a directory stream pointer), which is very similar to how standard I/O works. - Stateful Reading (
readdir): Reading a directory is stateful because the OS maintains an internal cursor. Every time you callreaddir(), the OS reads the current directory entry, returns adirentstructure (which contains the file's name and inode number), and automatically advances the cursor to the next file. - Memory Management: The pointer returned by
readdir()is statically managed by the library. You do not (and should not) callfree()on it.
Traversal
Read is stateful with a cursor
- Reading the same directory again gives back the next file in the directory
- You can even do "seek" to the beginning using
rewindir()
#include <dirent.h>
DIR* opendir(const char *dirname);
/* returns pointer to directory object */
struct dirent *readdir(DIR *dirp);
/* read successive entries in directory 'dirp' */
int closedir(DIR *dirp);
/* close directory stream */
void rewinddir(DIR *dirp);
/* reposition pointer to beginning of directory */
Notes:
- Strictly Read-Only: While you can read a directory's contents as much as you want, you can never open a directory for writing. Only the File System kernel code is allowed to safely write to directory structures (which it does behind the scenes when you use commands like
mkdir,rm, ortouch). - Resetting the Cursor (
rewinddir): Becausereaddir()advances the cursor, once you reach the end of the directory, subsequent calls will just returnNULL. If you need to make another pass through the directory, you don't need to close and reopen it. You can simply callrewinddir(), which acts like a "seek," instantly resetting the internal cursor back to the very first file in the directory. - Cleanup (
closedir): Just like regular files, directory streams consume system resources (under the hood, they use file descriptors). You must always callclosedir()when you are finished traversing to avoid resource leaks.
File System Organization
A disk drive is divided into one or more partitions.
- Each partition can contain a file system.
- The i-nodes are (generally) fixed-length entries that contain most of the information about a file.
Notes:
- Think of a partition, as laying out a filesystem
- You have a superblock
- An inode bitmap
- A block bitmap
- Then actually the array of inodes
- Each node is essentially a file (metadata + order sequence of data blocks)
- The rest of the blocks are data blocks
- These are the blocks that the metadata points to that may correspond to a file
Partition
- First, each sector/block is logically numbered 0, 1, ....
- The larger the disk, the more the sectors
- Then, the file system contains the following components:
| Super block | Bitmaps | inode table | Data Area |
|---|
| Component | Purpose |
|---|---|
| Superblock | Contains metadata about the file system. Size is FS dependent. (File system type, size, sizes of block groups and location of inode tables etc.) |
| Bitmaps | Use/free indicator of inodes & data blocks |
| inode table | An array of inode structs, where each struct contains info about a file object (e.g., size, owner id, last modification). Each inode has an unique number, which is also the index into the inode table |
| Data Area | Contains file content. Each file can be >=1 block |
struct inode
struct inode {
	unsigned long i_ino;
	umode_t i_mode;
	unsigned int i_nlink;
	uid_t i_uid;
	gid_t i_gid;
	loff_t i_size;
	time_t i_atime;
	time_t i_mtime;
	time_t i_ctime;
	union {
		struct ext3_inode_info ext3_i;
		struct ntfs_inode_info ntfs_i;
	} u;
};
struct ext3_inode_info {
	__u32 i_data[15];
};
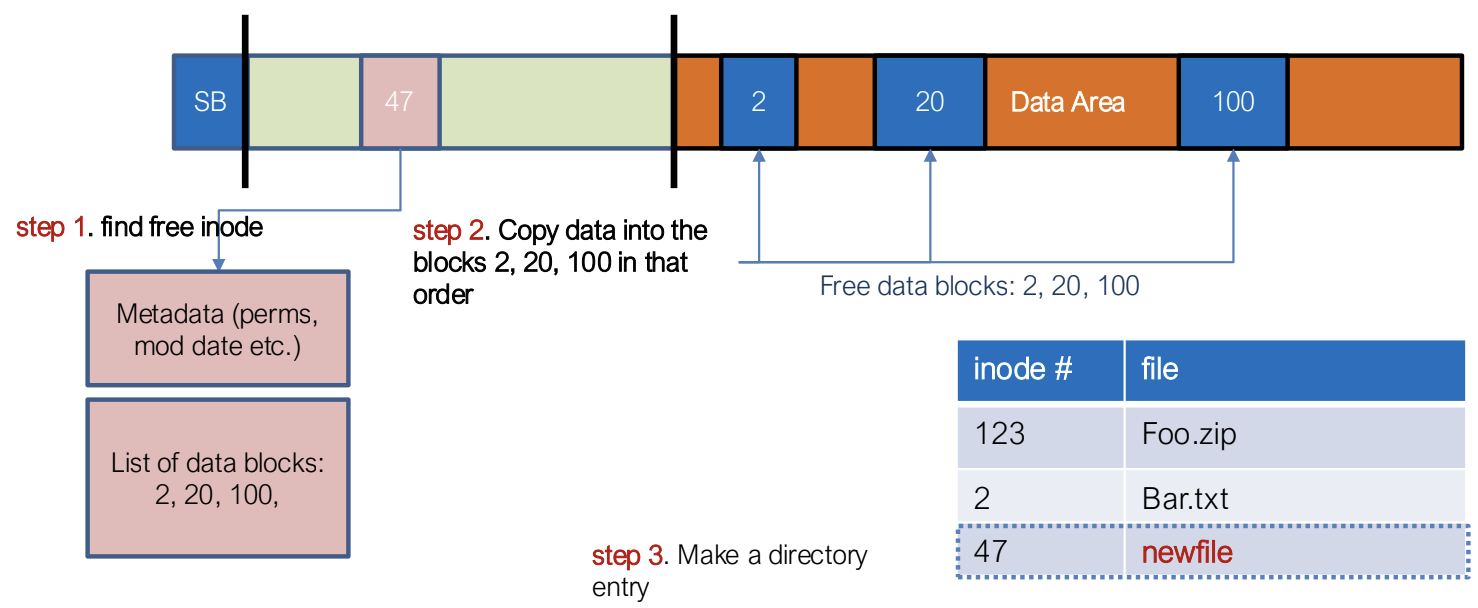
Steps for creating & writing a new file
- Store Properties:
- Look for a free inode and sore metadata (e.g., permissions, size, creation data) in the inode.
- Store data and record allocations:
- Look for enough free disk blocks and copy content
- Update inode with block
#s
- Add file name to directory:
- Store the (inode#, filename) pair in the directory entry
- You could crash anywhere. The FS provides all-or-nothing guarantee.
Example:
Let us create a file called "newfile" that is 12 KB in size. A disk block is 4 KB .
First, we need a free inode to put the file metadata, then find 3 free disk blocks to put the actual data
Steps for reading a file
- Search the current directory for the file name and extract its inode
- Locate and read the inode
- Find the data block number from there
- Read each data block in sequence and output that
This is how the cat file command works.
The output goes to stdout.
inode's features: protection
File owner/creator should be able to control:
- what can be done by whom
Types of access:
- Read
- Write
- Execute
- Append- ?
- Delete-w on file and wx on dir
- List-r on dir
Block indirection
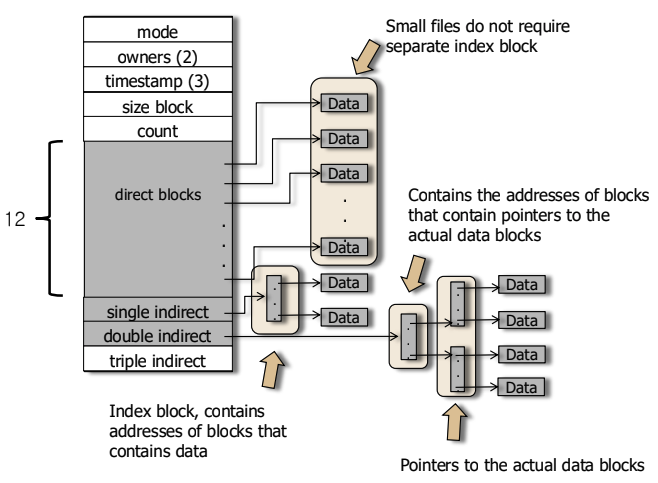
File Structure: Indexed Allocation
Notes:
- How do you store big files in an inode? how does UNIX do it?
- The Core Problem: An inode is a small, fixed-size data structure. So, how does UNIX manage to store the block locations for massive files (like a 4 GB video) inside such a tiny space?
- The UNIX Strategy (Optimize for the Common Case): UNIX designers discovered through experimentation that the vast majority of files on a system are actually very small. Therefore, the inode is designed to be extremely fast for small files, while using a "fan-out" pointer system (Indexed Allocation) to accommodate huge files when necessary.
- Level 1: Direct Blocks: The inode directly contains 12 block pointers. These point straight to the physical data blocks that make up the file's content. If we assume a standard block size of 4 KB, these 12 pointers can perfectly store any file up to 48 KB (12×4 KB) without needing any extra mapping structures.
- Level 2: Single Indirect: If the file exceeds 48 KB, the OS uses the "single indirect" pointer. This pointer does not point to data; instead, it points to a regular disk block that is completely filled with more pointers. If a 4 KB block can hold 1,024 pointers (assuming each pointer is a 4-byte integer), this single indirect block can map out an additional 4 MB of file data (1024×4 KB).
- Level 3: Double Indirect: If the file is even larger, the inode uses a "double indirect" pointer. This points to a block of pointers, which point to more blocks of pointers, which finally point to the actual data blocks. This creates a massive fan-out of 1024×1024 (roughly 1 million) data blocks, adding another 4 GB of capacity to the file.
- Level 4: Triple Indirect: For truly gigantic files, a triple indirect pointer adds a third tier of indirection (pointers to pointers to pointers to data), fanning out to add an enormous 4 TB of capacity.
Block indirection
- Direct block pointers: the block number points to the actual data block that contains the file data. In UNIX there are 12 direct block pointers.
- Indirect block pointers: this block number doesn't contain real file data. Instead, it has a set of references to blocks that may further contain references/data.
- Single indirect pointer: the indirect block contains a set of of direct data block numbers.
- Double indirect pointer: the indirect block contains a set of single indirect block numbers.
- Triple indirect pointer: the indirect block will contain a set of double indirect block numbers.
Why use block indirection?
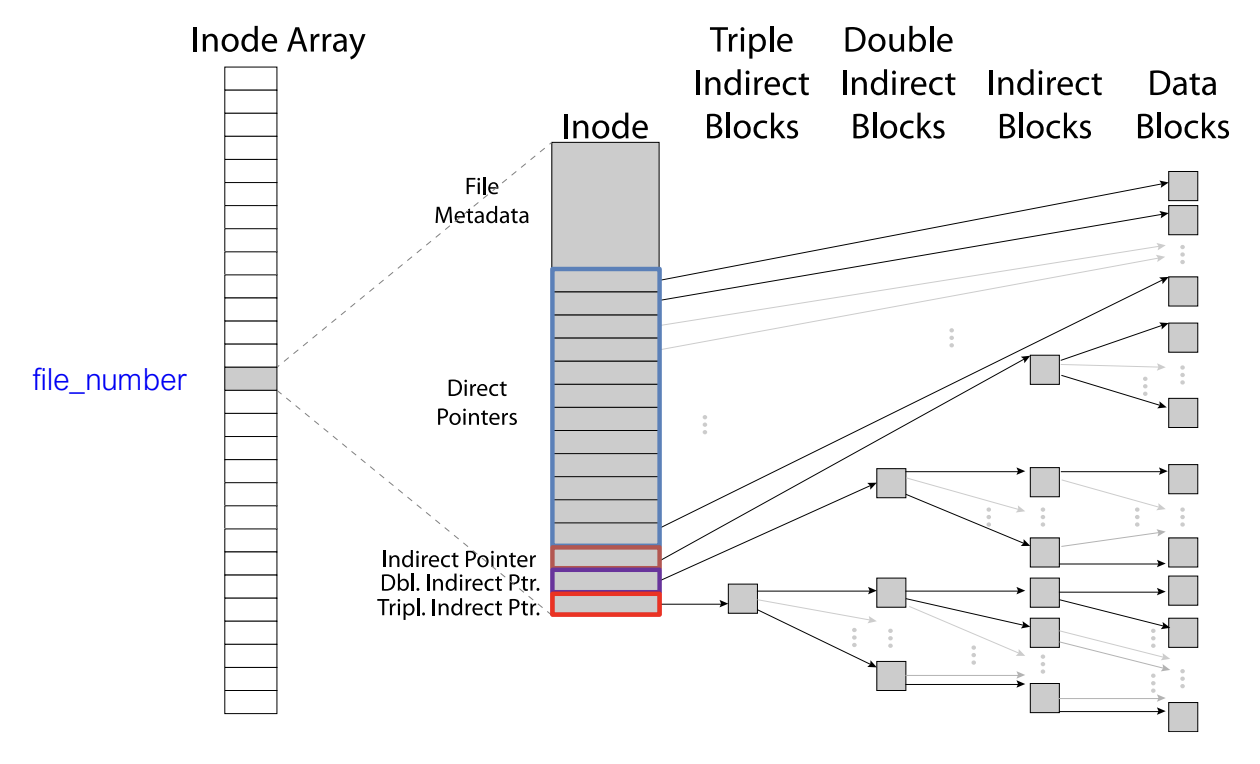
- You have blocks that contains pointers to double indirect blocks, then these container pointers to singly indirect blocks, then these actually contain pointers to actual disk blocks
FFS: Data Storage
Small files: 12 pointers direct to data blocks:
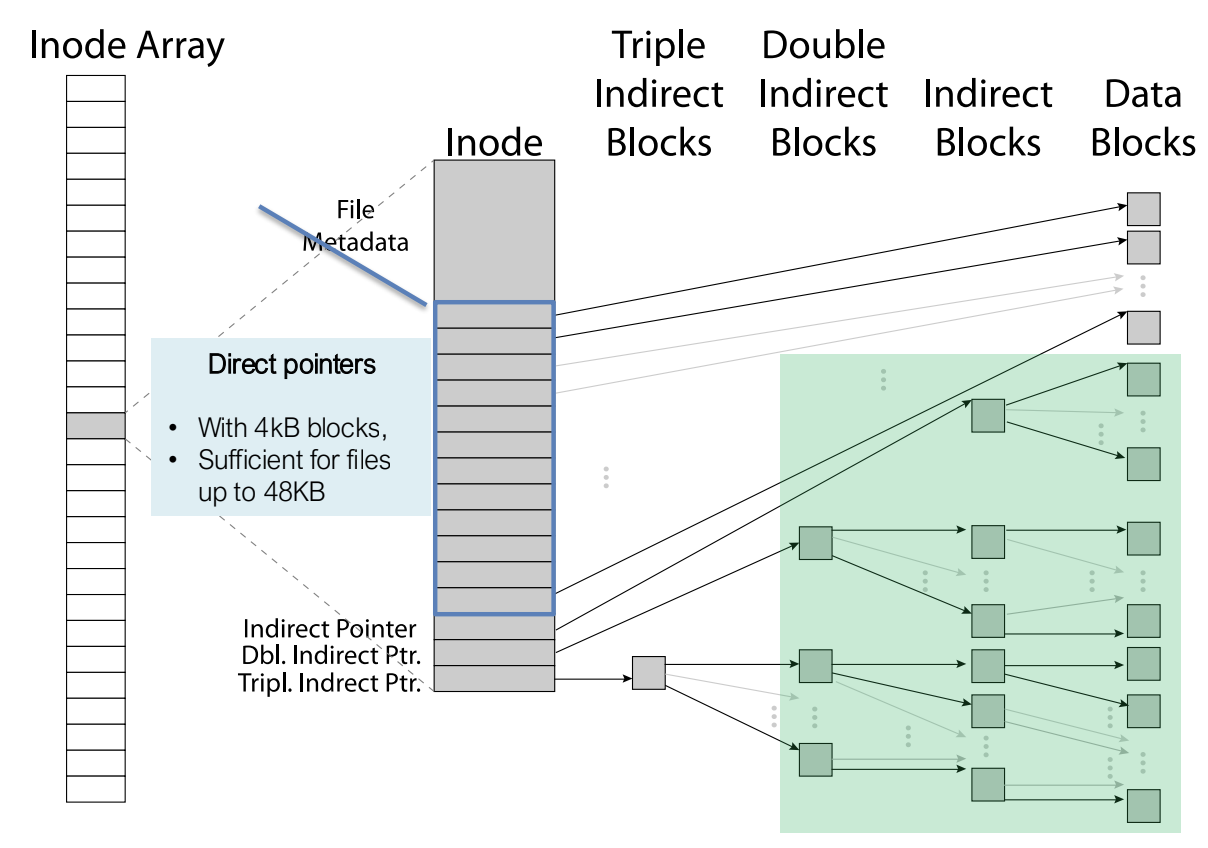
- For small files up to 48KB you do not need any indirect blocks
Large files: 1,2,3 level indirect pointers:
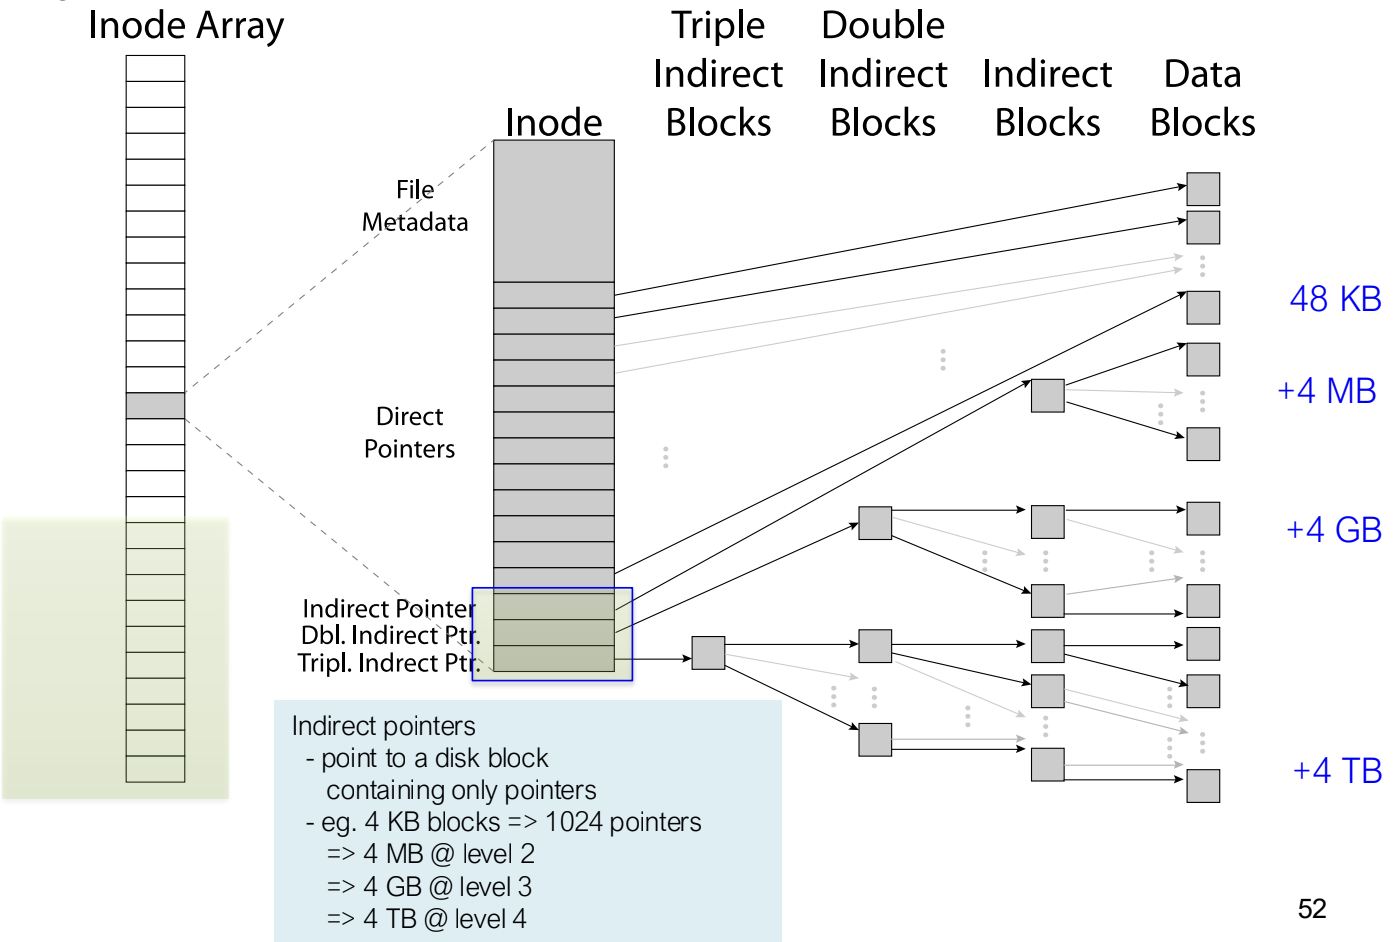
- What is the maximum file size in this file system layout?
- You have 12 direct data blocks, each is 4K
- You have 48KB that correspond to direct disk block pointers
- Then you have 1 indirect block`
- If you consider that each disk block is 1 int, then you have 1024 disk blocks that can be addressed by one indirect block
- 1K * 4KB = +4 MB
- If you consider that each disk block is 1 int, then you have 1024 disk blocks that can be addressed by one indirect block
- A doubly indirect pointer will fan out by one more level
- Now the number of blocks that you can address is:
- 1K * 1K * 4KB = +4 GB
- Now the number of blocks that you can address is:
- Similarly a triple indirect block
- Will give you:
- 1K * 1K * 1K * 4KB = +4TB
- Will give you:
- You have 12 direct data blocks, each is 4K
- So the total size of a file can be:
- 4TB + 4GB + 4MB + 48KB
Files: Big Picture
Notes:
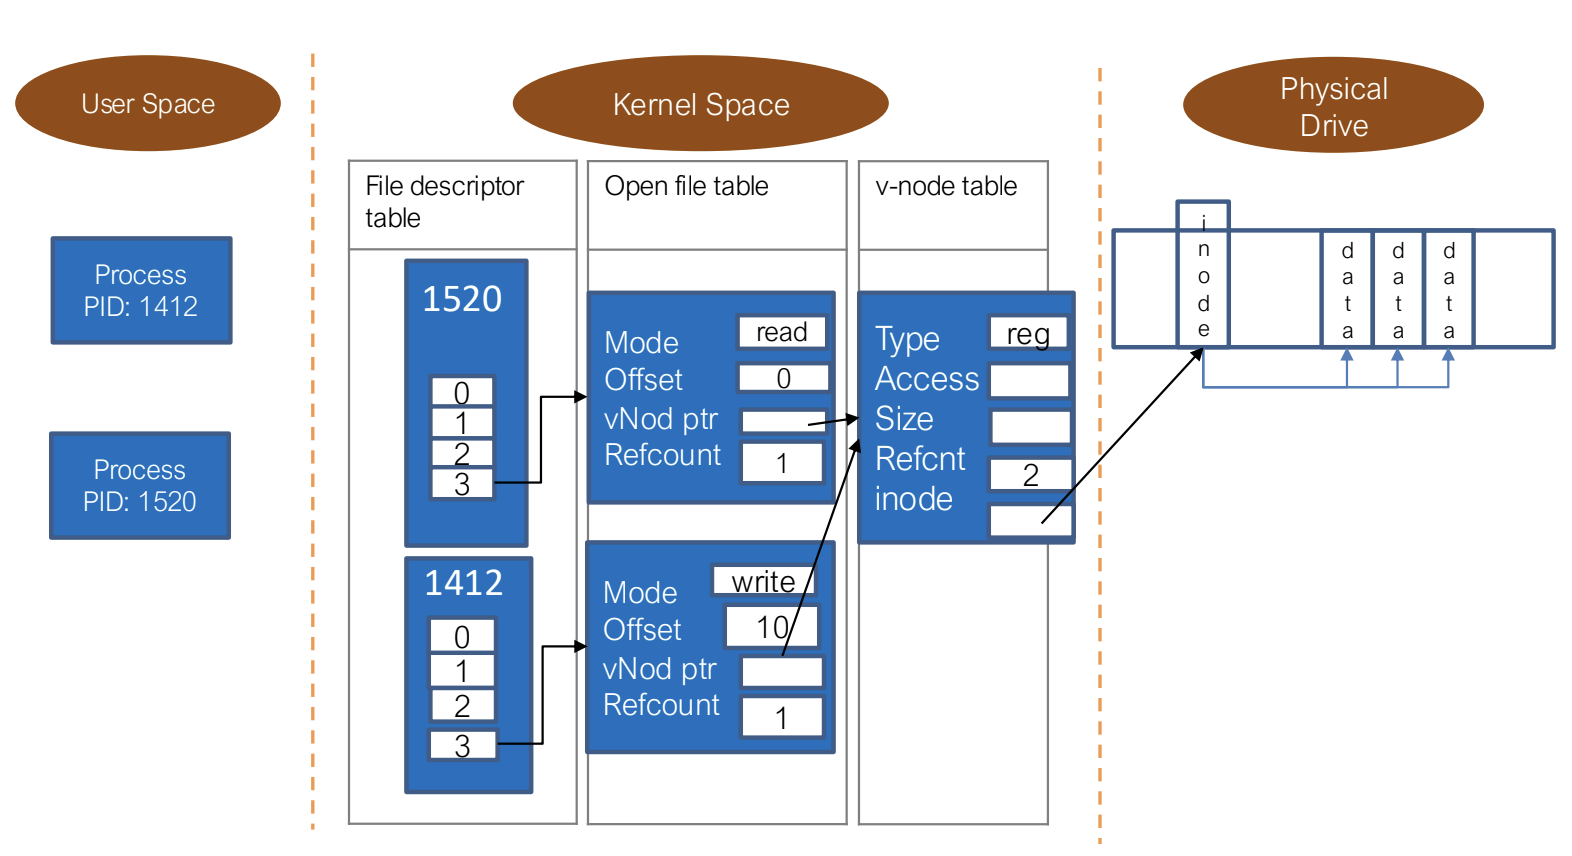
- The Core Concept (The Three-Table Architecture): To bridge the gap between a simple integer in your program (the file descriptor) and the actual physical bytes on the hard drive, UNIX utilizes a strict 3-level table architecture.
- Table 1: The File Descriptor Table (Per-Process): Every individual process has its own private array of file descriptors. When you use a file descriptor (like
fd = 2), it is simply acting as an index into this local array. The entry at this index contains a pointer to the next table. - Table 2: The Open File Table (System-Wide): This table is shared among all running processes in the system. This is where the OS stores the stateful session data for an opened file. Most importantly, it stores the File Cursor (the current byte offset of where you left off reading/writing) and the reference count (how many FDs are pointing to this session).
- Table 3: The v-node / Inode Table (System-Wide): The Open File Table entry points to a v-node table entry, which represents the actual, physical file object in the file system. This entry contains the file's metadata (permissions, owner) and the actual inode number.
- The Execution Flow (Example): When your program executes a
read(fd, buffer, 100):- The OS looks up
fdin your process's File Descriptor Table. - It follows the pointer to the Open File Table to find your current file offset (e.g., "start reading at byte 4096").
- It follows the next pointer to the v-node/inode, which gives the OS access to the direct/indirect disk block pointers.
- The OS "chases" those pointers to find the exact physical sectors on the hard drive, reads the bytes into your buffer, and finally advances the File Cursor in the Open File Table by 100 bytes.
- The OS looks up